Showing posts with label REST. Show all posts

Monday, 27 May 2019

SLiMSuite release v1.8.1 (2019-05-27)

SLiMSuite release v1.8.1 (2019-05-27) is now on GitHub and Zenodo:

This update has fast-forwarded the SLiMSuite release to v1.8.1 to be consistent with the tools/slimsuite.py wrapper script. A top level SLiMSuite.py file can now be run to access the main tools and functions of the package. The REST servers have also been updated to run this version of the code.

This release of SLiMSuite contains a number of updates related to the REST servers and some new tools, notably SAMPhaser long read diploid phasing algorithm, and BUSCOMP BUSCO compiler and comparison tool. See release notes (below) for more details.

SLiMSuite updates

Updates in extras/:

• rje_pydocs: Updated from Version 2.16.7.
→ Version 2.16.8: Updated to to parse https.
→ Version 2.16.9: Tweaked docstring parsing.

Updates in libraries/:

• rje: Updated from Version 4.19.0.
→ Version 4.19.1: Added code for catching non-ASCII log filenames.
→ Version 4.20.0: Added quiet mode to log object and output of errors to stderr. Fixed rankList(unique=True)
→ Version 4.21.0: Added hashlib MD% functions.
→ Version 4.21.1: Fixed bug where silent=T wasn't running silent.

• rje_blast_V2: Updated from Version 2.22.2.
→ Version 2.23.3: Fixed LocalIDCut error for GABLAM and QAssemble stat filtering.

• rje_db: Updated from Version 1.9.0.
→ Version 1.9.1: Updated logging of adding/removing fields: default is now when debugging only.

• rje_disorder: Updated from Version 1.2.0.
→ Version 1.3.0: Switched default behaviour to be md5acc=T.
→ Version 1.4.0: Fixed up disorder=parse and disorder=foldindex.
→ Version 1.5.0: Added iupred2 and anchor2 parsing from URL using accnum. Made default disorder=iushort2.

• rje_genbank: Updated from Version 1.5.3.
→ Version 1.5.4: Added recognition of *.gbff for genbank files.

• rje_obj: Updated from Version 2.2.2.
→ Version 2.3.0: Added quiet mode to object and stderr output.
→ Version 2.4.0: Added vLog() and bugLog() methods.
→ Version 2.4.1: Fixed bug where silent=T wasn't running silent.

• rje_paf: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Initial working version. Compatible with GABLAM v2.30.0 and Snapper v1.7.0.
→ Version 0.2.0: Added endextend=X : Extend minimap2 hits to end of sequence if with X bp [10]
→ Version 0.3.0: Added mapsplice mode for dealing with transcript mapping.
→ Version 0.3.1: Correct PAF splicing bug.
→ Version 0.4.0: Added TmpDir and forking for GABLAM conversion.
→ Version 0.5.0: Added uniquehit=T/F : Option to use *.hitunique.tdt table of unique coverage for GABLAM coverage stats [False]

• rje_ppi: Updated from Version 2.8.1.
→ Version 2.9.0: Added ppiout=FILE : Save pairwise PPI file following processing (if rest=None) [None]

• rje_qsub: Updated from Version 1.9.2.
→ Version 1.9.3: Updates the order of the qsub -S /bin/bash flag.

• rje_rmd: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.

• rje_samtools: Updated from Version 1.20.0.
→ Version 1.20.1: Fixed mlen bug. Added catching of unmapped reads in SAM file. Fixed RLen bug. Changed softclip defaults.
→ Version 1.20.2: Fixed readlen coverage bug and acut bug.

• rje_seq: Updated from Version 3.25.0.
→ Version 3.25.1: Fixed -long_seqids retrieval bug.
→ Version 3.25.2: Fixed 9spec filtering bug.

• rje_seqlist: Updated from Version 1.29.0.
→ Version 1.30.0: Updated and improved DNA2Protein.
→ Version 1.31.0: Added genecounter to rename option for use with other programs, e.g. PAGSAT.
→ Version 1.31.1: Fixed edit bug when not in DNA mode.
→ Version 1.32.0: Added genomesize and NG50/LG50 to DNA summarise.
→ Version 1.32.1: Fixed LG50/L50 bug.

• rje_sequence: Updated from Version 2.6.0.
→ Version 2.7.0: Added shift=X to maskRegion() for 1-L input. Fixed cterminal maskRegion.

• rje_slimcore: Updated from Version 2.9.0.
→ Version 2.10.0: Added seqfilter=T/F : Whether to apply sequence filtering options (goodX, badX etc.) to input [False]
→ Version 2.10.1: Fixed default results file bug.
→ Version 2.10.2: Improved handling and REST output of disorder scores.
→ Version 2.11.0: Modified qregion=X,Y to be 1-L numbering.

• rje_slimlist: Updated from Version 1.7.3.
→ Version 1.7.4: Modified concetanation of SLiMSuite results to use "|" in place of "#" for better compatibility.

• rje_uniprot: Updated from Version 3.25.0.
→ Version 3.25.1: Fixed proteome download bug following Uniprot changes.
→ Version 3.25.2: Fixed Uniprot protein extraction issues by using curl. (May not be a robust fix!)

Updates in tools/:

• buscomp: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Basic working version.
→ Version 0.2.0: Functional version with basic RMarkdown HTML output.
→ Version 0.3.0: Added ratefas=FILELIST: Additional fasta files of assemblies to rate with BUSCOMPSeq (No BUSCO run) [].
→ Version 0.4.0: Implemented forking and tidied up output a little.
→ Version 0.5.0: Updated genome stats and RMarkdown HTML output. Reorganised assembly loading and proeccessing. Added menus.
→ Version 0.5.1: Reorganised code for clearer flow and documentation. Unique and missing BUSCO output added.
→ Version 0.5.2: Dropped paircomp method and added Rmarkdown control methods. Updated Rmarkdown descriptions. Updated log output.
→ Version 0.5.3: Tweaked log output and fixed a few minor bugs.
→ Version 0.5.4: Deleted some excess code and tweaked BUSCO percentage plot outputs.
→ Version 0.5.5: Fixed minlocid bug and cleared up minimap temp directories. Added LnnIDxx to BUSCOMP outputs.
→ Version 0.5.6: Added uniquehit=T/F : Option to use *.hitunique.tdt table of unique coverage for GABLAM coverage stats [False]
→ Version 0.6.0: Added more minimap options, changed defaults and dev generation of a table changes in ratings from BUSCO to BUSCOMP.
→ Version 0.6.1: Fixed bug that was including Duplicated sequences in the buscomp.fasta file. Added option to exclude from BUSCOMPSeq compilation.
→ Version 0.6.2: Fixed bug introduced that had broken manual group review/editing.
→ Version 0.7.0: Updated the defaults in the light of test analyses. Tweaked Rmd report.
→ Version 0.7.1: Fixed unique group count bug when some genomes are not in a group. Fixed running with non-standard options.
→ Version 0.7.2: Added loadsummary=T/F option to regenerate summaries and fixed bugs running without BUSCO results.

• comparimotif_V3: Updated from Version 3.13.0.
→ Version 3.14.0: Modified memsaver mode to take different input formats.

• gablam: Updated from Version 2.29.0.
→ Version 2.30.0: Added mapper=X : Program to use for mapping files against each other (blast/minimap) [blast]
→ Version 2.30.1: Fixed BLAST LocalIDCut error for GABLAM and QAssemble stat filtering.

• gopher: Updated from Version 3.4.3.
→ Version 3.5.0: Added separate outputs for trees with different alignment programs.
→ Version 3.5.1: Added capacity to run DNA GOPHER with tblastx. (Not tested!)
→ Version 3.5.2: Added acc=LIST as alias for uniprotid=LIST and updated docstring for REST to make it clear that rest=X needed.

• haqesac: Updated from Version 1.12.0.
→ Version 1.13.0: Modified qregion=X,Y to be 1-L numbering.

• pagsat: Updated from Version 2.4.0.
→ Version 2.5.0: Reduced the executed code when mapfas=T assessment=F. (Recommended first run.) Added renaming.
→ Version 2.5.1: Added recognition of *.gbff for genbank files.
→ Version 2.6.0: Added mapper=X : Program to use for mapping files against each other (blast/minimap) [blast]
→ Version 2.6.1: Switch failure to find key report files to a long warning, not program exit.
→ Version 2.6.2: Fixed bugs with mapper=minimap mode and started adding more internal documentation.
→ Version 2.6.3: Fixed default behaviour to run report=T mode.
→ Version 2.6.4: Fixed summary table merge bug.
→ Version 2.6.5: Fixed compile path bug.
→ Version 2.6.6: Fixed BLAST LocalIDCut error for GABLAM and QAssemble stat filtering.
→ Version 2.6.7: Generalised compile path bug fix.
→ Version 2.6.8: Added ChromXcov fields to PAGSAT Compare.

• pingu_V4: Updated from Version 4.9.0.
→ Version 4.9.1: Fixed Pairwise parsing and filtering for more flexibility of input. Fixed fasid=X bug and ppiseqfile names.
→ Version 4.10.0: Added hubfield and spokefield options for parsing hublist.

• qslimfinder: Updated from Version 2.2.0.
→ Version 2.3.0: Modified qregion=X,Y to be 1-L numbering.

• samphaser: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Updated SAMPhaser to be more memory efficient.
→ Version 0.2.0: Added reading of sequence and generation of SNP-altered haplotype blocks.
→ Version 0.2.1: Fixed bug in which zero-phasing sequences were being excluded from blocks output.
→ Version 0.3.0: Made a new unzip process.
→ Version 0.4.0: Added RGraphics for unzip.
→ Version 0.4.1: Fixed MeanX bug in devUnzip.
→ Version 0.4.2: Made phaseindels=F by default: mononucleotide indel errors will probably add phasing noise. Fixed basefile R bug.
→ Version 0.4.3: Fixed bug introduced by adding depthplot code. Fixed phaseindels bug. (Wasn't working!)
→ Version 0.4.4: Modified mincut=X to adjust for samtools V1.12.0.
→ Version 0.4.5: Updated for modified RJE_SAMTools output.
→ Version 0.4.6: splitzero=X : Whether to split haplotigs at zero-coverage regions of X+ bp (-1 = no split) [100]
→ Version 0.5.0: snptable=T/F : Output filtered alleles to SNP Table [False]
→ Version 0.6.0: Converted haplotig naming to be consistent for PAGSAT generation. Updated for rje_samtools v1.21.1.
→ Version 0.7.0: Added skiploci=LIST and phaseloci=LIST : Optional list of loci to skip phasing []
→ Version 0.8.0: poordepth=T/F : Whether to include reads with poor track probability in haplotig depth plots (random track) [False]

• seqmapper: Updated from Version 2.2.0.
→ Version 2.3.0: Added GABLAM-free method.

• seqsuite: Updated from Version 1.19.1.
→ Version 1.20.0: Added rje_paf.PAF.
→ Version 1.21.0: Added NG50 and LG50 to batch summarise.
→ Version 1.22.0: Added BUSCOMP to programs.
→ Version 1.23.0: Added rje_ppi.PPI to programs.

• slimbench: Updated from Version 2.18.2.
→ Version 2.18.3: Added better handling of motifs without TP occurrences for OccBench. Added minocctp=INT.
→ Version 2.18.4: Fixed ELMBench rating bug.
→ Version 2.18.5: Fixed Balanced=F bug.
→ Version 2.19.0: Implemented dataset=LIST: List of headers to split dataset into. If blank, will use datatype defaults. []

• slimfarmer: Updated from Version 1.9.0.
→ Version 1.10.0: Added appending contents of jobini file to slimsuite=F farm commands.

• slimfinder: Updated from Version 5.3.4.
→ Version 5.3.5: Fixed slimcheck and advanced stats models bug.
→ Version 5.4.0: Modified qregion=X,Y to be 1-L numbering.

• slimparser: Updated from Version 0.5.0.
→ Version 0.5.1: Minor docs and bug fixes.
→ Version 0.6.0: Improved functionality as replacement pureapi with rest=jobid and rest=check functions.

• slimsuite: Updated from Version 1.7.1.
→ Version 1.8.0: Added BUSCOMP and basic test function.
→ Version 1.8.1: Updated documentation and added IUPred2. General tidy up and new example data for protocols paper.

• smrtscape: Updated from Version 2.2.2.
→ Version 2.2.3: Fixed bug where SMRT subreads are not returned by seqlist in correct order. Fixed RQ=0 bug.

• snapper: Updated from Version 1.6.1.
→ Version 1.7.0: Added mapper=minimap setting, compatible with GABLAM v2.30.0 and rje_paf v0.1.0.


© RJ Edwards 2019. Last modified 27 May 2019.

Monday, 2 July 2018

SLiMSuite release v1.4.0 (2018-06-02) now oline

SLiMSuite release v1.4.0 (2018-07-02) is now on GitHub. The REST servers have also been updated to run this version of the code.

This release of SLiMSuite contains a number of updates related to the REST servers and some new pre-release dev tools in the main repo (but not the *.tgz file).

SeqList has updated sequence summary statistics and grep-based redundancy removal for large genomes.

One major bug fix is a change to parsing Uniprot entries from the website following a change in behaviour of the API.

SLiMSuite updates

Updates in extras/:

• rje_pydocs: Updated from Version 2.16.3.
→ Version 2.16.4: Tweaked formatDocString.
→ Version 2.16.5: Added general commands to docstring HTML for REST servers.
→ Version 2.16.6: Modified parsing to keep DocString for SPyDarm runs.
→ Version 2.16.7: Fixed T/F/FILE option type parsing bug.

Updates in libraries/:

• rje_blast_V2: Updated from Version 2.18.0.
→ Version 2.19.0: Added blastgz=T/F : Whether to zip and unzip BLAST results files [False]
→ Version 2.19.1: Fixed erroneous i=-1 blastprog over-ride but not sure why it was happening.
→ Version 2.20.0: Added localGFF output
→ Version 2.21.0: Added blasttask=X setting for BLAST -task ['megablast']
→ Version 2.22.0: Added dust filter for blastn and setting blastprog based on blasttask
→ Version 2.22.1: Added trimLocal error catching for exonerate issues.
→ Version 2.22.2: Fixed GFF attribute case issue.

• rje_db: Updated from Version 1.8.6.
→ Version 1.9.0: Added comment output to saveToFile().

• rje_disorder: Updated from Version 0.8.
→ Version 1.0.0: Added random disorder function and elevated to v1.x as fully functional for SLiMSuite
→ Version 1.1.0: Added strict option for disorder method selection. Added minorder=X.
→ Version 1.2.0: Added saving and loading scores to IUScoreDir/.

• rje_gff: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Basic functional version.

• rje_hpc: Updated from Version 1.1.
→ Version 1.1.1: Added output of subjob command to log as run.

• rje_html: Updated from Version 0.2.1.
→ Version 0.3.0: Added optional loading of javascript files and stupidtable.js?dev default.

• rje_qsub: Updated from Version 1.9.1.
→ Version 1.9.2: Modified qsub() to return job ID.

• rje_samtools: Updated from Version 1.19.2.
→ Version 1.20.0: Added parsing of BAM file - needs samtools on system. Added minsoftclip=X, maxsoftclip=X and minreadlen=X.

• rje_seq: Updated from Version 3.24.0.
→ Version 3.25.0: 9spec=T/F : Whether to treat 9XXXX species codes as actual species (generally higher taxa) [False]

• rje_seqlist: Updated from Version 1.25.0.
→ Version 1.26.0: Updated sequence statistics and fixed N50 underestimation bug.
→ Version 1.26.1: Fixed median length overestimation bug.
→ Version 1.26.2: Fixed sizesort bug. (Now big to small as advertised.)
→ Version 1.27.0: Added grepNR() method (dev only). Switched default to RevCompNR=T.
→ Version 1.28.0: Fixed second pass NR naming bug and added option to switch off altogether.
→ Version 1.29.0: Added maker=T/F : Whether to extract MAKER2 statistics (AED, eAED, QI) from sequence names [False]

• rje_slimcalc: Updated from Version 0.9.3.
→ Version 0.10.0: Added extra disorder methods to slimcalc.

• rje_taxonomy: Updated from Version 1.2.0.
→ Version 1.3.0: taxtable=T/F : Whether to output results in a table rather than text lists [False]

• rje_tree: Updated from Version 2.15.0.
→ Version 2.16.0: 9spec=T/F : Whether to treat 9XXXX species codes as actual species (generally higher taxa) [False]
→ Version 2.16.1: Modified NSF reading to cope with extra information beyond the ";".

• rje_uniprot: Updated from Version 3.24.1.
→ Version 3.24.2: Updated HTTP to HTTPS. Having some download issues with server failures.
→ Version 3.25.0: Fixed new Uniprot batch query URL. Added onebyone=T/F : Whether to download one entry at a time. Slower but should maintain order [False].

• rje_zen: Updated from Version 1.3.2.
→ Version 1.4.0: Added some more words and "They fight crime!" structure.

Updates in tools/:

• gablam: Updated from Version 2.28.3.
→ Version 2.29.0: Added localGFF=T/F output

• gasp: Updated from Version 1.4.
→ Version 2.0.0: Upgraded to rje_obj framework for REST server.

• gasp_V1: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 1.0: Improved version with second pass.
→ Version 1.1: Improved OO. Restriction to descendant AAs. (Good for BAD etc.)
→ Version 1.2: No Out Object in Objects
→ Version 1.3: Added more interactive load options
→ Version 1.4: Minor tweaks to imports.

• gopher: Updated from Version 3.4.2.
→ Version 3.4.3: Added checking and warning if no bootstraps for orthtree.

• haqesac: Updated from Version 1.11.0.
→ Version 1.12.0: 9spec=T/F : Whether to treat 9XXXX species codes as actual species (generally higher taxa) [False]

• multihaq: Updated from Version 1.3.0.
→ Version 1.4.0: Added SLiMFarmer batch forking if autoskip=F and i=-1.
→ Version 1.4.1: Added haqblastdir=PATH: Directory in which MultiHAQ BLAST2FAS BLAST runs will be performed [./HAQBLAST/]

• pagsat: Updated from Version 2.3.3.
→ Version 2.3.4: Fixed full.fas request bug.
→ Version 2.4.0: Added PAGSAT compile mode to generate comparisons of reference chromosomes across assemblies.

• seqsuite: Updated from Version 1.14.0.
→ Version 1.14.1: Added zentest for testing the REST servers.
→ Version 1.15.0: Added GASP to REST servers.
→ Version 1.16.0: Add rje_gff.GFF to REST servers.
→ Version 1.17.0: Added batch summarise mode.
→ Version 1.18.0: Added rje_apollo.Apollo to REST servers.
→ Version 1.19.0: Tweaked the output of batch summarise, adding Gap% and reducing dp for some fields.
→ Version 1.19.1: Fixed GapPC summarise output to be a percentage, not a fraction.

• slimbench: Updated from Version 2.14.0.
→ Version 2.14.1: Fixed up PPIBench results loading.
→ Version 2.14.2: Fixed ByCloud bug.
→ Version 2.15.0: Updated assessSearchMemSaver() to handle different data types properly. dombench not yet supported.
→ Version 2.16.0: Added ppi hub/slim summary and motif filter for assessment datasets post-rating (still count as OT)
→ Version 2.16.1: Bug-fixing PPI generation from pairwise PPI files.
→ Version 2.16.2: Fixed benchmarking setup bug.
→ Version 2.16.3: Fixed bug when Hub-PPI links fail during PPI Benchmarking.
→ Version 2.17.0: Added output of missing datasets when balanced=T.
→ Version 2.18.0: Added dev OccBench with improved ratings and more efficient results handling. (dev only)
→ Version 2.18.1: Added additional OccBench options (bymotif, occsource, occspec)
→ Version 2.18.2: Fixed problem with source file selection ignoring i=-1.

• slimfarmer: Updated from Version 1.7.0.
→ Version 1.8.0: jobforks=X : Number of forks to pass to farmed out run if >0 [0]
→ Version 1.9.0: daisychain=X : Chain together a set of qsub runs of the same call that depend on the previous job.

• slimfinder: Updated from Version 5.3.3.
→ Version 5.3.4: Fixed terminal (^/$) musthave bug.

• slimsuite: Updated from Version 1.7.0.
→ Version 1.7.1: Added error raising for protected REST alias data.

• smrtscape: Updated from Version 2.2.1.
→ Version 2.2.2: Added dna=T to all SeqList object generation.

• snapper: Updated from Version 1.6.0.
→ Version 1.6.1: Fixed bug for reducing to unique-unique pairings that was over-filtering.


© RJ Edwards 2018. Last modified 2 Jul 2018.

Tuesday, 16 January 2018

SLiMSuite REST server is back up

The REST server is back up. The development server is currently having an upgrade and should not be used.

SLiMSuite REST server is currently down

The SLiMSuite REST server is experiencing some technical difficulties at the moment. It will hopefully be back up soon.

Thursday, 10 December 2015

BioInfoSummer2015 SLiMSuite Workshop

Dr Richard Edwards, University of New South Wales
Thursday 10th December 2015

Session outline

Click for slides.

Part I: Theory

  • Introduction to workshop
  • What are SLiMs?
  • What is SLiMSuite

Part II: Practice

  • Installing/running SLiMSuite
  • Data types and main input formats
  • Motif discovery using the SLiMSuite REST Servers
  • Motif discovery using the SLiMScape app for Cytoscape

Additional help and documentation

General information about SLiMs and motif discovery can be found in the literature. Some good places to start are the recent ELM 2016 paper and our 2015 Methods in Molecular Biology review as well as the SLiMScape app paper:

For information about SLiMSuite, please visit the EdwardsLab webpage and the SLiMSuite blog. Help and documentation for the REST servers can also be found at the REST homepage. If in doubt, please email: richard.edwards@unsw.edu.au.

Several EdwardsLab publications also cover motifs and SLiMSuite tools.

Installing/Running SLiMSuite

NOTE: For this workshop, you do not need to install SLiMSuite. You will need Cytoscape and the SLiMScape app for the later parts.


The current SLiMSuite release is 2015-11-30 and can be downloaded by clicking the button (left).

In addition to the tarball available via the links above, SLiMSuite is now available as a GitHub repository (right).

See also: Installation and Setup.

For this workshop, we will primarily be running the tools (and looking at pre-generated results) via the online servers:

Data types and main input formats

From a computer science perspective, input and output for SLiMSuite is just plain ASCII text. This makes it easy to plug SLiMSuite into existing scripts and pipelines - and manually view/edit any input or output files if required. However, “plain text” is not very informative, and SLiMSuite actually deals with a lot of different formats of plain text (from a “human formatting” rather than “file type” point of view). The documentation is currently in the process of being updated to better reflect these formats but some commandline options will still simply list FILE, FILES or FILELIST as input parameters: see the accompanying descriptions to see what format these should be. Ask if it’s not clear! (File format documentation will also be added to the SLiMSuite blog, so check there.)

Within SLiMSuite, each file type has a distinct “file extension” that denotes the file type. Note that these are not enforced for input, although some programs may not always recognise the right format if a different extension is used. If you get odd input behaviour/errors that you do not understand, see if changing the file extensions helps. If you want a common file extension to be auto-recognised, let me know and I might be able to add it. SLiMSuite file extensions will not necessarily be recognised by other programs. NOTE: Operating systems will sometimes hide file extensions by default. If you are getting very confused, or have problems of extra *.txt extensions on everything, try changing the system settings. (And/or becoming familiar with command-line file manipulation.)

The main input formats for SLiM discovery are:

  • A source of protein sequence data. This could be a protein FASTA file, a Uniprot plain text file, or a list of Uniprot accession numbers to download. For some tools, a single Uniprot accession number will work.
  • A source of motif (regular expression) definitions. This is only required if looking for known (or other pre-defined) motifs and/or wanting to compare a set of de novo predictions with known motifs. A number of different formats are accepted for motif input, including SLiMFinder (summary) results and ELM downloads. The simplest/easiest is a plain text file of regular expressions. For more on motif regular expression formats, please see Edwards and Palopoli 2015.

Common motif discovery tasks

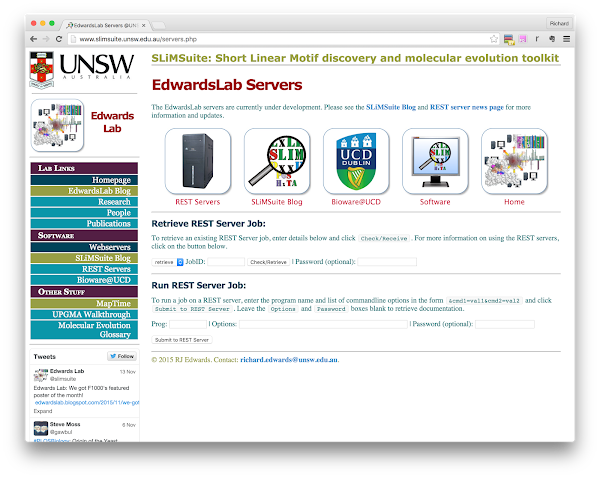
Jobs can be run and retrieved at: http://www.slimsuite.unsw.edu.au/servers.php. (This is a bit easier than making the URL directly, although this is also an option as we will see.)

NOTE: Some of the jobs take a while to run and the SLiMSuite servers have limited resources. It would therefore be useful if you could click on the example JobID links rather than trying to run every example REST command yourself. The first output tab (and the log tab) will show you the run times for that job, so you can see which jobs are fast or slow before you experiment.


Task 1: Find known SLiMs in a protein (ELM/SLiMProb)

ELM. Visit http://http://www.elm.eu.org/ and enter your protein of choice as Uniprot identifier or accession number in the box. (Identifiers will auto-complete and fill in some extra details.) For non-Uniprot protein sequences, you can also enter fasta format.

Try this now with P03070 (LT_SV40) or P03254 (E1A_ADE02). Each of them should have a True Positive LIG_Rb_LxCxE_1 motif.

SLiMProb. We can do a similar search using the SLiMProb REST server (paste the contents of the grey box onto the end of the http://rest.slimsuite.unsw.edu.au/ URL):

slimprob&uniprotid=E1A_ADE02&motifs=elm

JobID: 15120800029

NOTE: The ELM alias currently searches the 2015 ELM classes.


Task 2: Find custom SLiMS in a protein (SLiMProb)

slimprob&uniprotid=E1A_ADE02&motifs=LxCxE,PxDLS

JobID: 15120800031


Task 3: Finding proteome-wide occurrence of a motif using Bioware (SLiMSearch)

The SLiMSearch server is accessible at: http://slim.ucd.ie/slimsearch/. This has been recently updated to Version 4 and now brings in a lot of information, so it is recommended that you read the Help pages for the server.

Example (LIG_CtBP_PxDLS_1): http://slim.ucd.ie/rest/#/slimsearch/annotations?jobId=7R8Tvssm9HEdjWW7jQsgEHUfP0VlHdR6

Human protein PRDM16 is particularly interesting: it does not have an annotated ELM but does match a region annotated to interact with CTBP1. (See the Region column - Expand the instance Feature annotations for a clearer look.) This kind of search can be a good way of identifying new instances of known motifs - some of which may be in the literature but may not have yet made it into database annotation.

The ELM definition for this motif P[LVIPME][DENS][LM][VASTRG] is very degenerate with a lot of hits - over-prediction is a big problem in motif discovery. We can try to make the definition a little tighter as the expense of some instances, using another tool called SLiMMaker:

slimmaker&peptides=LIG_CtBP_PxDLS_1&iterate=T&align=F&minfreq=0.67&minseq=2

JobID: 15120600004

Repeating the SLiMSearch analysis with the redefined motif (P[EILMV][DN]L[ARST]) gives a greater density of known ELMs (see the Motif column) in the top ranked motifs: http://slim.ucd.ie/rest/#/slimsearch/annotations?jobId=L41BRpXQ1oTD6ByDuUSqjWbQZ22WBKbw.


Task 4: Predicting novel SLiMs de novo in a set of proteins (SLiMFinder)

SLiMFinder is designed to look for convergently evolved motifs that are shared between unrelated proteins. For example, we can look at the proteins known (in ELM) to contain the LIG_PCNA_PIPBox_1. As SLiMs are generally in disordered regions, we will switch disorder masking on with dismask=T, which uses IUPred to predict globular regions, which are masked out:

slimfinder&uniprotid=LIG_PCNA_PIPBox_1&dismask=T

JobID: 15120800001

(We will look at the UPC and motif cloud output among others.)


Task 5: Identifying known motifs from de novo predictions (CompariMotif)

When you have a lot of motif predictions, it can be tiresome and error-prone to manually scan them for things that look familiar. SLiMSuite has a tool called CompariMotif, which compares sets of motifs for similarity.

The comparimotif server can take motif files/lists (like SLiMProb or SLiMFinder output directly. These are given to the &motifs and/or &searchdb options: if no &searchdb is given then the input motifs are searched against themselves. (This can be useful if clouding goes a bit wrong.)

To pass the output of one server to another, use the format: &cmd=jobid:XXXXXX:OUTFMT, where XXXXXX is the Job ID and OUTFMT is the desired output format. E.g.:

comparimotif&motifs=jobid:15120800001:main&searchdb=LIG_PCNA_PIPBox_1

JobID: 15120900004

The server is currently in development so output is not sorted usefully yet. This is more of a problem if searching against many SLiMs:

comparimotif&motifs=jobid:15120800001:main&searchdb=elm

JobID: 15120900005

The best advice is to save the compare output table (retrieve&jobid=15120900005&outfmt=compare), open it up in Excel and sort on Score. Alternatively, use the CompariMotif server at http://bioware.ucd.ie.


Task 6: SLiM prediction with conservation masking (SLiMFinder)

Masking is important as it reduces the search space. It can also reduce the signal if it incorrectly masks some true positives but for larger datasets the reduction in "noise" can be more important. As well as dismask=T/F there are several other masking options in SLiMSuite:

  • low complexity masking (ON by default)
  • N-terminal methionines (ON by default)
  • conservation-based masking (OFF by default)
  • Uniprot feature masking (OFF by default)
  • Motif masking (OFF by default)

For custom sequence input, there is also the option for custom masking based on upper/lower case. For now, we will just look at conservation masking, as this has been shown to improve sensitivity in PPI data. For example, a 2013 compilation of CTBP1 interactors does not yield a significant motif:

slimfinder&uniprotid=CTBP1&dismask=T&runid=CtBP1-DisMask

JobID: 15120900002

But if consmask=T is also switched on:

slimfinder&uniprotid=CTBP1&dismask=T&consmask=T&runid=CtBP1-ConsMask

JobID: 15120900003

The importance of correcting for evolutionary relationships

The UPC correction can be switched off with efilter=F. Many motif prediction tools calculate estimated expectations without such correction. This can result is massive biases due to shared evolutionary history, which swamp any convergent SLiM evolution signal, for example with the LIG_CtBP_PxDLS_1 ELM proteins:

slimfinder&uniprotid=LIG_CtBP_PxDLS_1&dismask=T&runid=CtBP-NoEFilter&efilter=F

JobID: 15120800036


Task 7: Look for enrichment or depletion of motifs in a set of proteins (SLiMProb)

We can investigate why the PxDLS motif did not come back with just disorder masking by looking at its enrichment using SLiMProb. When given multiple proteins, SLiMProb will use the same UPC correction as SLiMFinder but also return statistics without UPC correction and simply treating all the sequences as one giant sequence. It can, for example, be used to investigate different definitions of a motif:

slimprob&uniprotid=CTBP1&dismask=T&runid=CtBP1-DisMask&motifs=PxDLS,P[LVIPME][DENS][LM][VASTRG],Px[DE][LM][ST]

JobID: 15120900016

In this case, we can see that even though the "true" motif has the most support, it is also expected to occur more by chance. It is enriched, but not enough to survive the multiple testing correction of SLiMChance.

Though not of interest here, the pUnd statistics can be used to look for depletion/avoidance of a particular motif in a dataset.


Task 8: Find novel motifs from a conservation pattern (SLiMPrints)

Patterns of evolutionary conservation can also be used to directly identify regions of proteins that look like motifs. The tool we have developed for this is called SLiMPrints, which can be run at the Bioware SLiMPrints server. For example, we can look for motif-like regions in one of the CtBP PPI partners, FOG1_HUMAN (Q8IX07): http://bioware.ucd.ie/~compass/biowareweb/cgi-bin/PHP_helper_files/slimprintsInfo.php?jobId=e7GZLf

This protein has a bunch of significant motif-like regions, including the PxDLS motif region at rank 7: http://bioware.ucd.ie/~proviz/ProViz/alignmentViewer/drawer.php?uniprotid=Q8IX07&slim=GPIDL&slimpos=793&column=794.5&width=80&collapse=false

(Note how the precise motif is rarely returned by de novo predictors.)


Task 9: Using the SLiMScape app to visualise a server job

We're now going to fire up Cytoscape and have a quick look at the SLiMScape app. This is fairly well described in the paper, so we will just look at the main ways to run the server. If you've not used Cytoscape before, you'll want to visit the Cytoscape website and watch the introduction video, before installing it.

The simplest is to retrieve an existing run:

  1. In the SLiMFinder tab, enter 15120900003 in the Run ID box and hit Retrieve.
  2. Apply the default layout.
  3. Explore the results. Connections are UPC relationships in the data.

Task 10: Running QSLiMFinder through SLiMScape

Now let's imagine we had seen the SLiMPrints results from above for FOG1_HUMAN and knew that it interacted with CtBP1. We could ask the specific question if any motifs in FOG1_HUMAN were enriched in the rest of the PPI dataset. We do this by using QSLiMFinder and giving Q8IX07 as the query. (&query=Q8IX07 on the server.)

First, add a node to the network and change its name to Q8IX07. Enter this in the Query Sequence box then highlight all of the nodes before hitting Run QSLiMFinder:

JobID: 15120900007

This is the essence of molecular mimicry and we could use the same approach to see if E1A_ADE02 shares any motifs by adding P03254 and using it as a query:

JobID: 15120900008


Task 11: Building PPI networks for analysis

The most useful thing of having access to SLiMSuite through Cytoscape is to be able to use it to explore PPI networks and select nodes for analysis. There are in-built tools to get PPI data into Cytoscape. For SLiMSuite, the ID must be a Uniprot ID or accession number, or a Node must have "Uniprot" attribute.

The SLiMSuite REST server also provides some methods for getting PPI data into Cytoscape (and/or for use on the server), using the PINGU server. This is still under development and so the documentation of the available PPI data is currently limited, but just get in touch if you want to use it. (Currently human only.)

PPI data is retrieved by entering one or more gene symbols as a &hublist, optionally along with a &ppisource (see the ppisource alias):

pingu&hublist=CTBP1,CTBP2&ppisource=intact

JobID: 15120900009

This can be used directly for &uniprotid input using the &rest=uniprot output:

slimfinder&uniprotid=jobid:15120900009:uniprot&dismask=T&consmask=T&runid=CtBP1and2

JobID: 15120900011

Alternatively, the PPI data can be imported into Cytoscape using the pairwise table:

  1. Start a new session. (Later you can workout how to import and merge networks.)
  2. Import network from URL: http://rest.slimsuite.unsw.edu.au/retrieve&jobid=15120900009&rest=pairwise
  3. Rename the HubUni and SpokeUni fields to name and attribute them to Source Node and Target Node attributes. Make Hub the Source, Spoke the Target and Evidence the Interaction Type then import.
  4. Select the nodes that are shared interactors of both CtBP proteins.
  5. Modify the masking settings to include disorder, conservation and feature masking.
  6. Hit Run:

JobID: 15120900013

Monday, 7 December 2015

New SLiMSuite REST Servers

Since the move to UNSW in 2013, the Bioware SLiMSuite servers and REST servers have been undergoing some much needed TLC. As part of this process, a new set of UNSW REST servers were introduced and online with the 2015-06-01 SLiMSuite release.

An overview of how the REST servers work is given on the REST Homepage. The available tools are listed at the REST Tools page. The main ones - accessible through the SLiMScape app for Cytoscape are (or support):

The primary focus has been setting up new servers to be accessed via a RESTful-style interface whereby a URL can be directly given to the server and used to either download results directly (if accessing programmatically) or view in a web browser. As with the main programs, these servers use plain text inputs and outputs wherever. Whilst this probably makes proper computer scientists very unhappy, it should make it very easy to incorporate SLiMSuite REST functions into your own scripts - you only need to learn how to parse text. (It also makes it easy for me to swap input sources.) If you don’t want to write your own, SLiMParser is provided in the SLiMSuite download to do this for you.

The other design consideration that has gone into the REST servers is to make them run as much like the commandline versions as possible: (1) they use the same code; (2) they use the same commandline options, parsed from the URL. This means that (a) you should easily be able to reproduce server results on your own system, and (b) new functions (and bug fixes) should become quickly available via the REST servers.

To save the need for constructing complex URLs, there is a simple on-size-fits-all form at the EdwardsLab server page. Over time, tool-specific forms will be established. Currently, this only exists for SLiMMaker.

As ever, if something about the new servers misbehaves or does not make sense - or you really want some new functions - please get in touch.

Monday, 1 June 2015

SLiMSuite release 2015-06-01 now available

A new download of SLiMSuite (release 2015-06-01) is now available. This is the first release in the new git repository at https://github.com/slimsuite/SLiMSuite. A tarball slimsuite.2015-06-01.tgz is also available, containing the same code. Once unpacked, it should be possible to pull down additional updates with git. (This release corresponds to the UCD svn repo r895.)

The major change since the last release is a general tidying of the repository in preparation for going on GitHub and tidying documentation for the new online help via the SLiMSuite REST Server:

for:

To try out the new documentation for a given program, replace sitemap in the box and click View Documentation. Leaving sitemap in the box will list all modules, which can then be clicked on.

The old PDF Manuals are still included in the release and can be accessed from the EdwardsLab Software page. These will be updated eventually but the focus is currently on getting module docstrings and the online help up-to-date. As ever, please get in touch if you have any questions.

This release also sees the addition of a new tool, SLiMParser for running/parsing the new REST servers. SLiMMaker has also undergone some improvements and now features: (1) basic peptide alignment prior to motif generation; (2) extension of degenerate sites using an “equivalence” list of similar amino acids.

A full list of updates is given below.

Updates since previous release

Updates in tools/:

• gablam: Updated from Version 2.16.1.
→ Version 2.17.0: Added localalnfas=T/F : Whether to output local alignments to *.local.fas fasta file (if local=T) [False]
→ Version 2.17.1: Fixed bug where query and hit lengths were not being output for fullblast.
→ Version 2.18.0: Added blaste filtering to be applied to existing BLAST results.
→ Version 2.19.0: Added maxall=X limits to all-by-all analyses. Added qassemble=T.
→ Version 2.19.1: Fixed handling of basefile and results generation for blastres=FILE.
→ Version 2.19.2: Modified output to be in rank order.

• gopher: Updated from Version 3.4.
→ Version 3.4.1: Fixed stripXGap issue. (Why was this being implemented anyway?). Added REST output.

• haqesac: Updated from Version 1.10.
→ Version 1.10.1: Tweaked QryVar interactivity.
→ Version 1.10.2: Corrected typos and disabled buggy post-HAQESAC data reduction.

• multihaq: Updated from Version 1.2.
→ Version 1.2.1: Updated documentation to include the HAQESAC reference.
→ Version 1.2.2: Switched default to keepblast=T. Added forking blasta=X command to BLAST.

• peptcluster: Updated from Version 1.4.
→ Version 1.5.0: Added peptalign=T/F/X function for aligning peptides using regex or minimal gap addition. Added REST.
→ Version 1.5.1: Updated REST output. Removed peptide redundancy.

• pingu_V4: Updated from Version 4.3.
→ Version 4.4.0: Converted ppicompile=T to ppicompile=LIST.
→ Version 4.5.0: Added hublist=LIST : List of hub genes to restrict pairwise PPI to, and pairwise parsing.

• qslimfinder: Updated from Version 2.0.
→ Version 2.1.0: Added PTMData and PTMList options.

• seqsuite: Updated from Version 1.4.0.
→ Version 1.5.0: Added extatic.ExTATIC and revert.REVERT. NOTE: Dev only.
→ Version 1.5.1: Added 'seq' as alias for 'rje_seq' - want to avoid rje_ prefix requirements.
→ Version 1.6.0: Added mitab and rje_mitab for MITAB parsing.
→ Version 1.6.1: Added extra error messages.
→ Version 1.7.0: Added pingu_V4.PINGU.
→ Version 1.8.0: Added rje_pacbio.PacBio.

• slimbench: Updated from Version 2.8.0.
→ Version 2.8.1: Removed use of Protein name for ELM Uniprot entries due to problems mapping old IDs.
→ Version 2.9.0: Added SLiMMaker ELM reduction table and output.
→ Version 2.9.1: Enabled download only with generate=F benchmark=F.
→ Version 2.10.0: Add generation of table mapping PPIBench dataset generation.

• slimfarmer: Updated from Version 1.4.1.
→ Version 1.4.2: Fixed log transfer issues due to new #VIO line. Better handling of crashed runs.

• slimfinder: Updated from Version 5.1.
→ Version 5.1.1: Modified alphabet handling and fixed musthave bug.
→ Version 5.2.0: Added PTMList and PTMData modes (dev only).

• slimmaker: Updated from Version 1.2.0.
→ Version 1.3.0: Added varlength option to identify gaps in aligned peptides and generate variable length motif.
→ Version 1.3.1: Fixed varlength option to work with end of peptide gaps. (Gaps ignored completely - should not be there!)
→ Version 1.4.0: Add iteration REST output.
→ Version 1.4.1: Add unmatched peptides REST output.
→ Version 1.4.2: Fixed bug with variable length wildcards at start of sequence.
→ Version 1.5.0: Added peptalign=X functionality, using PeptCluster peptide alignment.
→ Version 1.6.0: Added equiv=LIST : List (or file) of TEIRESIAS-style ambiguities to use [AGS,ILMVF,FYW,FYH,KRH,DE,ST]
→ Version 1.6.1: Fixed peptide case bug.

• slimparser: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.0.1: Fixed RestKeys bug.
→ Version 0.1.0: Added retrieval and parsing of existing server job. Added password.
→ Version 0.2.0: Added API access to REST server if restin is REST call (i.e. starts with http:)
→ Version 0.2.1: Added PureAPI output of API REST call returned text.
→ Version 0.3.0: Added parsing of input files to give to rest calls.
→ Version 0.3.1: Fixed issue that had broken REST server full output.

• slimprob: Updated from Version 2.2.0.
→ Version 2.2.1: Updated REST output.
→ Version 2.2.2: Modified input to allow motif=X in addition to motifs=X.
→ Version 2.2.3: Tweaked basefile setting and citation.

• slimsuite: Updated from Version 1.3.0.
→ Version 1.4.0: Added RLC and Disorder progs to call SLiMCore. Added CompariMotif.
→ Version 1.5.0: Added peptcluster and peptalign calls.

Updates in extras/:

• file_monster: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 1.0: Initial Working version
→ Version 1.1: Broadened away from strict extension-based scavenging to whole file names with wildcards
→ Version 1.2: Added DirSum function and updated FileMonster slightly.
→ Version 1.3: Added redundant file cleanup
→ Version 1.4: Added skiplist and purgelist
→ Version 1.5: Added rename function (to replace rename.pl Perl module)
→ Version 1.6: Minor bug fix.
→ Version 2.0: Major reworking with new object making use of rje_db tables etc. Old functions to be ported with time.
→ Version 2.1: Added dirsum function.
→ Version 2.2: Added fixendings=FILELIST to convert Mac \\r into UNIX \\n

• prodigis: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 0.1: Added probability calculations based on hydrophobicity, serine and cysteine.
→ Version 0.2: Added cysteine count and cysteine weighting.

• rje_glossary: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 1.0: Working version, including text setup for webserver.
→ Version 1.1: Added href=T option to add external hyperlinks for and [text] in descriptions [True]
→ Version 1.2: Added recognition of _italics_ markup.
→ Version 1.3: Fixed minor italicising bug.
→ Version 1.4: Added keeporder=T/F to maintain input order (e.g. for MapTime).

• rje_itunes: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 0.1: Added Plays/Track, default Album Artist and topHTML() method.

• rje_phos: Created/Renamed/moved.
→ Version 0.0: Initial Compilation. Basic pELM parsing done.
→ Version 0.1: Added phosBLAST method.

• rje_pydocs: Updated from Version 2.14.0.
→ Version 2.15.0: Added parsing and generation of "pages" for new rest server docs functions.
→ Version 2.15.1: Tweaked formatting of outfmt and docstring documentation.
→ Version 2.15.2: Tweaked formatting of docstring documentation.
→ Version 2.15.3: Fixed URL formatting of docstring documentation.
→ Version 2.16.0: Added Webserver tab to doc parsing from settings/*.form.
→ Version 2.16.1: Added parsing of imports within a try/except block. (Cannot be on same line as try: or except:)
→ Version 2.16.2: Tweaked makePages() output.

• rje_seqplot: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.

• rje_ssds: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.

• rje_yeast: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.

• wormpump: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.

Updates in libraries/:

• rje: Updated from Version 4.13.1.
→ Version 4.13.2: Removed excess REST HTML methods.
→ Version 4.13.3: Added uselower=False to dataDict() method.
→ Version 4.13.4: Added maxrep=X to listCombos() method.
→ Version 4.14.0: Added listToDict() method.
→ Version 4.15.1: Fixed matchExp method to be able to handline multilines. (Shame re.DOTALL doesn't work!)

• rje_blast_V2: Updated from Version 2.7.
→ Version 2.7.1: Added capacity to keep alignments following GABLAM calculations.
→ Version 2.7.2: Fixed bug with hitToSeq fasta output for rje_seqlist.SeqList objects.
→ Version 2.8.0: A more significant BLAST e-value setting will filter read results.
→ Version 2.9.0: Added qassemble=T/F : Whether to fully assemble query stats from all hits [False].
→ Version 2.9.1: Updated default BLAST and BLAST+ paths to '' for added modules.

• rje_db: Updated from Version 1.7.1.
→ Version 1.7.2: Fixed numerical join issue during Table.compress().
→ Version 1.7.3: Added lower case enforcement of headers for reading tables from file.
→ Version 1.7.4: Added optional restricted Field set for output.
→ Version 1.7.5: Added more error messages and tableNames() method.

• rje_ensembl: Updated from Version 2.14.
→ Version 2.15.0: Added capacity to download/process a section of Ensembl with speclist=LIST.
→ Version 2.15.1: Improved error handling for too many FTP connections: still need to fix problem!
→ Version 2.15.2: Trying to improve speed of Uniprot parsing for EnsLoci.

• rje_genbank: Updated from Version 1.2.2.
→ Version 1.3.0: Added split viral output.
→ Version 1.3.1: Fixed bug in split viral output.

• rje_html: Updated from Version 0.1.
→ Version 0.2.0: Added delimited text to HTML table conversion.
→ Version 0.2.1: Updated default CSS to http://www.slimsuite.unsw.edu.au/stylesheets/slimhtml.css.

• rje_mitab: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Added complex=LIST : Complex identifier prefixes to expand from mapped PPI [complex]
→ Version 0.1.1: Fixed Evidence/IType parsing bug for BioGrid/Intact.
→ Version 0.2.0: Added splicevar=T/F option.

• rje_obj: Updated from Version 2.1.0.
→ Version 2.1.1: Removed excess REST HTML methods.
→ Version 2.1.2: Tweaked glist cmdRead warnings.

• rje_qsub: Updated from Version 1.6.1.
→ Version 1.6.2: Updated module list: blast+/2.2.30,clustalw,clustalo,fsa,mafft,muscle,pagan,R/3.1.1

• rje_scoring: Updated from Version -.

• rje_seq: Updated from Version 3.21.0.
→ Version 3.22.0: Added loading sequences from provided sequence files contents directly, bypassing file reading.
→ Version 3.22.1: Fixed problem if seqin is blank, triggering odd Uniprot download.
→ Version 3.23.0: Add speclist to reformat options.

• rje_seqlist: Updated from Version 1.10.0.
→ Version 1.11.0: Added more dna2prot reformatting options.

• rje_slim: Updated from Version 1.9.
→ Version 1.10.0: Added varlength option to makeSlim() method.
→ Version 1.10.1: Fixed varlength and terminal position compatibility.
→ Version 1.10.2: Fixed issue of [] returns.
→ Version 1.10.3: Fixed makeSlim bug with variable length wildcards at start of sequence.
→ Version 1.11.0: Added splitMotif() function.
→ Version 1.12.0: Added equiv to makeSlim() function.

• rje_slimcore: Updated from Version 2.6.1.
→ Version 2.7.0: Updating MegaSLiM function to work with REST server. Allow megaslim=seqin. Added iuscoredir=PATH and protscores=T/F.
→ Version 2.7.1: Modified iuscoredir=PATH and protscores=T/F to work without megaslim. Fixed UPC/SLiMdb issue for GOPHER.
→ Version 2.7.2: Fixed iuscoredir=PATH to stop raising errors when file not previously made.
→ Version 2.7.3: Fixed serverend message error.

• rje_slimhtml: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 0.3: Added code for making Random Dataset pages
→ Version 0.4: Updated UPC pages and added additional front pages.
→ Version 0.5: Split front page into front and full. Added GO tabs/pages.
→ Version 0.6: Added XGMML output.
→ Version 0.7: Modified output for HumSF10 and HAPPI analysis.
→ Version 0.8: Added SVG output. Integrated better with HAPPI code.
→ Version 0.9: Added SLiM Descriptions.

• rje_slimlist: Updated from Version 1.6.
→ Version 1.7.0: Added direct feeding of motif file content for loading (for REST servers).
→ Version 1.7.1: Modified input to allow motif=X in additon to motifs=X.
→ Version 1.7.2: Fixed bug that could not accept variable length motifs from commandline. Improved error message.

• rje_specificity: Updated from Version -.

• rje_tree: Updated from Version 2.11.0.
→ Version 2.11.1: Tweaked QryVar interactivity.
→ Version 2.11.2: Updated tree paths.

• rje_tree_group: Updated from Version -.

• rje_uniprot: Updated from Version 3.20.3.
→ Version 3.20.4: Fixed bug introduced by REST access modifications.
→ Version 3.20.5: Improved handling of downloads for uniprot IDs that have been updated (i.e. no direct mapping).
→ Version 3.20.6: Improved handling of zero accession numbers for extraction.
→ Version 3.20.7: Fixed uniformat default error.
→ Version 3.21.0: Added uparse=LIST option to try and accelerate parsing of large datasets for limited information.
→ Version 3.21.1: FullText is no longer stored in Uniprot object. Will need special handling if required.
→ Version 3.21.2: Fixed single uniprot extraction bug.
→ Version 3.21.3: Added REST datout to proteomes extraction.

• rje_xref: Updated from Version 1.3.0.
→ Version 1.3.1: Fixed xref list bug.
→ Version 1.4.0: Added optional Mapping dictionary for speeding up recurring mapping (should avoid if memsaver=F).
→ Version 1.5.0: Added stripvar=CDICT removal of variants using Field:Char list, e.g. Uniprot:-,GenPept:. []
→ Version 1.6.0: Added mapxref=LIST List of identifiers to map to KeyIDs using mapfields []

• rje_zen: Updated from Version 1.3.0.
→ Version 1.3.1: Added some more words.