Showing posts with label SLiMSuite. Show all posts
Showing posts with label SLiMSuite. Show all posts
Tuesday, 8 July 2025
SLiMSuite Servers out of action
Following a move out of academia and lack of ongoing funding, the SLiMSuite website and servers at UNSW are currently out of action. It is not clear at this point whether they will be restored, replaced, or permanently retired. SLiMSuite programs and code are still available from GitHub. Please get in touch if you have any questions during this transition period.

Thursday, 19 September 2024
SLiMSuite Release v1.12.0 (2024-09-19)
The current SLiMSuite release is v1.12.0 (2024-09-19) and can be downloaded by clicking the button (left).
In addition to the tarball available via the button (left), SLiMSuite is now available as a GitHub repository (right).

See also: Installation and Setup.
The main updates in SLiMSuite v1.12.0 are:
- Python3. The main tools in use have been updated and checked with Python3. Some older tools might still have bugs.
- BUSCOMP now has a new mode
phylofas=Tto generate output of compiled and renamed files for BUSCO-based phylogenomics. - DepthKopy has undergone several upgrades and will now rate Duplicated BUSCOs (TRUE/FALSE) based on depth, chunk up input for multithreaded processing, and collapse features by depth to estimate total copy number. KAT can now generate the kmer usage in an alternative assembly for comparison.
- DepthSizer has some miscellaneous bug fixes and the same parallisation added to DepthKopy.
- Diploidocus output has been updated for ChromSyn compatibility.
- NUMTFinder has had several coverage and depth bugs fixed.
- PAFScaff has been updated for rapid BUSCO-based mapping. Added
purechrom=Tto enable reciprocal PAFScaff runs for SharpClaw - SynBad has received multiple updates to enable BUSCO mapping and update the assembly map output to be compatible with Telociraptor.
- Telociraptor has received multiple updates to improve generation of tweaked assemblies from assembly maps. It also now features a chromosome sorting and renaming function based on size.
- DepthCharge has a new
minspan=INTminimum spanning bp at end of reads (trims from PAF alignments). - ChromSyn has undergone numerous updates and improvement: see the ChromSyn github for details.
NOTE: Several tools are now maintained and updated more regularly in their own GitHub repos.
Wednesday, 12 January 2022
SLiMSuite release v1.11.0 (2022-01-12)

SLiMSuite v1.11 sees the introduction of six genome assembly tools:
- DepthCharge = Genome assembly quality control and misassembly repair. DepthCharge is an assembly quality control and misassembly repair program. It uses mapped long read depth of coverage to charge through a genome assembly and identify coverage “cliffs” that may indicate a misassembly. If appropriate, it will then blast the assembly into fragment at those misassemblies.
- DepthKopy = DepthKopy: Read-depth based copy number estimation. DepthKopy applies the same single-copy read depth estimate as DepthSizer to estimate the copy number of different gene regions in a slightly modified version of the approach used in the basenji genome paper.
- DepthSizer = DepthSizer: Read-depth based genome size prediction. DepthSizer uses long-read depth profiles and BUSCO single-copy orthologues to predict genome size. DepthSizer works on the principle that Complete BUSCO genes should represent predominantly single copy (diploid read depth) regions along with some poor quality and/or repeat regions. Assembly artefacts and collapsed repeats etc. are predicted to deviate from diploid read depth in an inconsistent manner. Therefore, even if less than half the region is actually diploid coverage, the modal read depth is expected to represent the actual single copy read depth.
- GapSpanner = GapSpanner: Genome assembly gap long read support and reassembly tool. GapSpanner uses (or generates) a BAM file of long reads mapped to a genome assembly to assess assembly “gaps” for spanning read support. Optionally, reads spanning each gap can be extracted and re-assembled with Flye. If the new assembly spans the gap, crude gap-filling can be performed. This will be reversed if edits are not subsequently supported by spanning reads mapped onto the updated assembly.
- NUMTFinder = NUMTFinder: Nuclear mitochondrial fragment (NUMT) search tool. NUMTFinder uses a mitochondrial genome to search against genome assembly and identify putative NUMTs. NUMT fragments are then combined into NUMT blocks based on proximity.
- Taxolotl = Taxolotl: Genome assembly taxonomy summary and assessment tool. Taxolotl combines the MMseqs2 easy-taxonomy with GFF parsing to perform taxonomic analysis of a genome assembly (and any subsets given by taxsubsets=LIST) using an annotated proteome. Taxonomic assignments are mapped onto genes as well as assembly scaffolds and (if assembly=FILE is given) contigs.
Documentation for these tools can be found in their individual repos. Please note that individual repos may be ahead of the main SLiMSuite repo.
More information can also be found in the corresponding publications:
- Chen SH, Rossetto M, van der Merwe M, Lu-Irving P, Yap JS, Sauquet H, Bourke G, Amos TG, Bragg JG & Edwards RJ (accepted): Chromosome-level de novo genome assembly of Telopea speciosissima (New South Wales waratah) using long-reads, linked-reads and Hi-C. Molecular Ecology Resources. [Mol Ecol Res] [bioRxiv]
- Edwards RJ, Field MA, Ferguson JM, Dudchenko O, Keilwagen K, Rosen BD, Johnson GS, Rice ES, Hillier L, Hammond JM, Towarnicki SG, Omer A, Khan R, Skvortsova K, Bogdanovic O, Zammit RA, Aiden EL, Warren WC & Ballard JWO (2021): Chromosome-length genome assembly and structural variations of the primal Basenji dog (Canis lupus familiaris) genome. BMC Genomics 22:188 [BMC Genomics] [PubMed] [bioRxiv]
- Stuart KC*, Edwards RJ*, Cheng Y, Warren WC, Burt DW, Sherwin WB, Hofmeister NR, Werner SJ, Ball GF, Bateson M, Brandley MC, Buchanan KL, Cassey P, Clayton DF, De Meyer T, Meddle SL & Rollins LA (preprint): Transcript- and annotation-guided genome assembly of the European starling. bioRxiv 2021.04.07.438753; doi: 10.1101/2021.04.07.438753. [*Joint first authors] [bioRxiv]
See also the included release_notes.txt on GitHub for a full list of the python module updates since v1.9.0.
Sunday, 27 December 2020
SLiMSuite release v1.9.1 (2020-12-27)
SLiMSuite release v1.9.1 (2020-12-27) is now on GitHub and Zenodo:
- Edwards RJ (2020): SLiMSuite v1.9.1 (2020-12-27). Zenodo DOI: 10.5281/zenodo.3229523
SLiMSuite v1.9 sees the introduction of four genome assembly tools:
- Diploidocus = Diploid genome assembly analysis toolkit. Includes assembly cleanup (haplotig/artefact removal), genome size prediction and read depth copy number analysis.
- PAFScaff = Pairwise mApping Format reference-based scaffold anchoring and super-scaffolding. Uses minimap2 to map a genome assembly onto reference chromosomes.
- SAAGA = Summarise, Annotate & Assess Genome Annotations. Uses a reference proteome to summarise and assess genome annotations.
- SynBad = Synteny-based scaffolding adjustment tool for comparing two related genome assemblies and identify putative translocations and inversions between the two that correspond to gap positions. (Development only.)
There have also been significant updates to:
- BUSCOMP = BUSCO Compiler and Comparison tool. Used for genome assembly completeness estimates that are robust to sequence quality, and for compiling BUSCO results.
Other changes include some initial reformatting for Python3 compatibility. This is ongoing work; please report any odd behaviour.
See the included release_notes.txt for a full list of the python module updates since v1.8.1.
NOTE: At time of posting, the REST servers have not yet been updated with the latest version. This will happen soon.
Monday, 27 May 2019
SLiMSuite release v1.8.1 (2019-05-27)
SLiMSuite release v1.8.1 (2019-05-27) is now on GitHub and Zenodo:
- Edwards RJ (2019): SLiMSuite v1.8.1 (2019-05-27). Zenodo DOI: 10.5281/zenodo.3229523
This update has fast-forwarded the SLiMSuite release to v1.8.1 to be consistent with the tools/slimsuite.py wrapper script. A top level SLiMSuite.py file can now be run to access the main tools and functions of the package. The REST servers have also been updated to run this version of the code.
This release of SLiMSuite contains a number of updates related to the REST servers and some new tools, notably SAMPhaser long read diploid phasing algorithm, and BUSCOMP BUSCO compiler and comparison tool. See release notes (below) for more details.
SLiMSuite updates
Updates in extras/:
• rje_pydocs: Updated from Version 2.16.7.
→ Version 2.16.8: Updated to to parse https.
→ Version 2.16.9: Tweaked docstring parsing.
Updates in libraries/:
• rje: Updated from Version 4.19.0.
→ Version 4.19.1: Added code for catching non-ASCII log filenames.
→ Version 4.20.0: Added quiet mode to log object and output of errors to stderr. Fixed rankList(unique=True)
→ Version 4.21.0: Added hashlib MD% functions.
→ Version 4.21.1: Fixed bug where silent=T wasn't running silent.
• rje_blast_V2: Updated from Version 2.22.2.
→ Version 2.23.3: Fixed LocalIDCut error for GABLAM and QAssemble stat filtering.
• rje_db: Updated from Version 1.9.0.
→ Version 1.9.1: Updated logging of adding/removing fields: default is now when debugging only.
• rje_disorder: Updated from Version 1.2.0.
→ Version 1.3.0: Switched default behaviour to be md5acc=T.
→ Version 1.4.0: Fixed up disorder=parse and disorder=foldindex.
→ Version 1.5.0: Added iupred2 and anchor2 parsing from URL using accnum. Made default disorder=iushort2.
• rje_genbank: Updated from Version 1.5.3.
→ Version 1.5.4: Added recognition of *.gbff for genbank files.
• rje_obj: Updated from Version 2.2.2.
→ Version 2.3.0: Added quiet mode to object and stderr output.
→ Version 2.4.0: Added vLog() and bugLog() methods.
→ Version 2.4.1: Fixed bug where silent=T wasn't running silent.
• rje_paf: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Initial working version. Compatible with GABLAM v2.30.0 and Snapper v1.7.0.
→ Version 0.2.0: Added endextend=X : Extend minimap2 hits to end of sequence if with X bp [10]
→ Version 0.3.0: Added mapsplice mode for dealing with transcript mapping.
→ Version 0.3.1: Correct PAF splicing bug.
→ Version 0.4.0: Added TmpDir and forking for GABLAM conversion.
→ Version 0.5.0: Added uniquehit=T/F : Option to use *.hitunique.tdt table of unique coverage for GABLAM coverage stats [False]
• rje_ppi: Updated from Version 2.8.1.
→ Version 2.9.0: Added ppiout=FILE : Save pairwise PPI file following processing (if rest=None) [None]
• rje_qsub: Updated from Version 1.9.2.
→ Version 1.9.3: Updates the order of the qsub -S /bin/bash flag.
• rje_rmd: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
• rje_samtools: Updated from Version 1.20.0.
→ Version 1.20.1: Fixed mlen bug. Added catching of unmapped reads in SAM file. Fixed RLen bug. Changed softclip defaults.
→ Version 1.20.2: Fixed readlen coverage bug and acut bug.
• rje_seq: Updated from Version 3.25.0.
→ Version 3.25.1: Fixed -long_seqids retrieval bug.
→ Version 3.25.2: Fixed 9spec filtering bug.
• rje_seqlist: Updated from Version 1.29.0.
→ Version 1.30.0: Updated and improved DNA2Protein.
→ Version 1.31.0: Added genecounter to rename option for use with other programs, e.g. PAGSAT.
→ Version 1.31.1: Fixed edit bug when not in DNA mode.
→ Version 1.32.0: Added genomesize and NG50/LG50 to DNA summarise.
→ Version 1.32.1: Fixed LG50/L50 bug.
• rje_sequence: Updated from Version 2.6.0.
→ Version 2.7.0: Added shift=X to maskRegion() for 1-L input. Fixed cterminal maskRegion.
• rje_slimcore: Updated from Version 2.9.0.
→ Version 2.10.0: Added seqfilter=T/F : Whether to apply sequence filtering options (goodX, badX etc.) to input [False]
→ Version 2.10.1: Fixed default results file bug.
→ Version 2.10.2: Improved handling and REST output of disorder scores.
→ Version 2.11.0: Modified qregion=X,Y to be 1-L numbering.
• rje_slimlist: Updated from Version 1.7.3.
→ Version 1.7.4: Modified concetanation of SLiMSuite results to use "|" in place of "#" for better compatibility.
• rje_uniprot: Updated from Version 3.25.0.
→ Version 3.25.1: Fixed proteome download bug following Uniprot changes.
→ Version 3.25.2: Fixed Uniprot protein extraction issues by using curl. (May not be a robust fix!)
Updates in tools/:
• buscomp: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Basic working version.
→ Version 0.2.0: Functional version with basic RMarkdown HTML output.
→ Version 0.3.0: Added ratefas=FILELIST: Additional fasta files of assemblies to rate with BUSCOMPSeq (No BUSCO run) [].
→ Version 0.4.0: Implemented forking and tidied up output a little.
→ Version 0.5.0: Updated genome stats and RMarkdown HTML output. Reorganised assembly loading and proeccessing. Added menus.
→ Version 0.5.1: Reorganised code for clearer flow and documentation. Unique and missing BUSCO output added.
→ Version 0.5.2: Dropped paircomp method and added Rmarkdown control methods. Updated Rmarkdown descriptions. Updated log output.
→ Version 0.5.3: Tweaked log output and fixed a few minor bugs.
→ Version 0.5.4: Deleted some excess code and tweaked BUSCO percentage plot outputs.
→ Version 0.5.5: Fixed minlocid bug and cleared up minimap temp directories. Added LnnIDxx to BUSCOMP outputs.
→ Version 0.5.6: Added uniquehit=T/F : Option to use *.hitunique.tdt table of unique coverage for GABLAM coverage stats [False]
→ Version 0.6.0: Added more minimap options, changed defaults and dev generation of a table changes in ratings from BUSCO to BUSCOMP.
→ Version 0.6.1: Fixed bug that was including Duplicated sequences in the buscomp.fasta file. Added option to exclude from BUSCOMPSeq compilation.
→ Version 0.6.2: Fixed bug introduced that had broken manual group review/editing.
→ Version 0.7.0: Updated the defaults in the light of test analyses. Tweaked Rmd report.
→ Version 0.7.1: Fixed unique group count bug when some genomes are not in a group. Fixed running with non-standard options.
→ Version 0.7.2: Added loadsummary=T/F option to regenerate summaries and fixed bugs running without BUSCO results.
• comparimotif_V3: Updated from Version 3.13.0.
→ Version 3.14.0: Modified memsaver mode to take different input formats.
• gablam: Updated from Version 2.29.0.
→ Version 2.30.0: Added mapper=X : Program to use for mapping files against each other (blast/minimap) [blast]
→ Version 2.30.1: Fixed BLAST LocalIDCut error for GABLAM and QAssemble stat filtering.
• gopher: Updated from Version 3.4.3.
→ Version 3.5.0: Added separate outputs for trees with different alignment programs.
→ Version 3.5.1: Added capacity to run DNA GOPHER with tblastx. (Not tested!)
→ Version 3.5.2: Added acc=LIST as alias for uniprotid=LIST and updated docstring for REST to make it clear that rest=X needed.
• haqesac: Updated from Version 1.12.0.
→ Version 1.13.0: Modified qregion=X,Y to be 1-L numbering.
• pagsat: Updated from Version 2.4.0.
→ Version 2.5.0: Reduced the executed code when mapfas=T assessment=F. (Recommended first run.) Added renaming.
→ Version 2.5.1: Added recognition of *.gbff for genbank files.
→ Version 2.6.0: Added mapper=X : Program to use for mapping files against each other (blast/minimap) [blast]
→ Version 2.6.1: Switch failure to find key report files to a long warning, not program exit.
→ Version 2.6.2: Fixed bugs with mapper=minimap mode and started adding more internal documentation.
→ Version 2.6.3: Fixed default behaviour to run report=T mode.
→ Version 2.6.4: Fixed summary table merge bug.
→ Version 2.6.5: Fixed compile path bug.
→ Version 2.6.6: Fixed BLAST LocalIDCut error for GABLAM and QAssemble stat filtering.
→ Version 2.6.7: Generalised compile path bug fix.
→ Version 2.6.8: Added ChromXcov fields to PAGSAT Compare.
• pingu_V4: Updated from Version 4.9.0.
→ Version 4.9.1: Fixed Pairwise parsing and filtering for more flexibility of input. Fixed fasid=X bug and ppiseqfile names.
→ Version 4.10.0: Added hubfield and spokefield options for parsing hublist.
• qslimfinder: Updated from Version 2.2.0.
→ Version 2.3.0: Modified qregion=X,Y to be 1-L numbering.
• samphaser: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Updated SAMPhaser to be more memory efficient.
→ Version 0.2.0: Added reading of sequence and generation of SNP-altered haplotype blocks.
→ Version 0.2.1: Fixed bug in which zero-phasing sequences were being excluded from blocks output.
→ Version 0.3.0: Made a new unzip process.
→ Version 0.4.0: Added RGraphics for unzip.
→ Version 0.4.1: Fixed MeanX bug in devUnzip.
→ Version 0.4.2: Made phaseindels=F by default: mononucleotide indel errors will probably add phasing noise. Fixed basefile R bug.
→ Version 0.4.3: Fixed bug introduced by adding depthplot code. Fixed phaseindels bug. (Wasn't working!)
→ Version 0.4.4: Modified mincut=X to adjust for samtools V1.12.0.
→ Version 0.4.5: Updated for modified RJE_SAMTools output.
→ Version 0.4.6: splitzero=X : Whether to split haplotigs at zero-coverage regions of X+ bp (-1 = no split) [100]
→ Version 0.5.0: snptable=T/F : Output filtered alleles to SNP Table [False]
→ Version 0.6.0: Converted haplotig naming to be consistent for PAGSAT generation. Updated for rje_samtools v1.21.1.
→ Version 0.7.0: Added skiploci=LIST and phaseloci=LIST : Optional list of loci to skip phasing []
→ Version 0.8.0: poordepth=T/F : Whether to include reads with poor track probability in haplotig depth plots (random track) [False]
• seqmapper: Updated from Version 2.2.0.
→ Version 2.3.0: Added GABLAM-free method.
• seqsuite: Updated from Version 1.19.1.
→ Version 1.20.0: Added rje_paf.PAF.
→ Version 1.21.0: Added NG50 and LG50 to batch summarise.
→ Version 1.22.0: Added BUSCOMP to programs.
→ Version 1.23.0: Added rje_ppi.PPI to programs.
• slimbench: Updated from Version 2.18.2.
→ Version 2.18.3: Added better handling of motifs without TP occurrences for OccBench. Added minocctp=INT.
→ Version 2.18.4: Fixed ELMBench rating bug.
→ Version 2.18.5: Fixed Balanced=F bug.
→ Version 2.19.0: Implemented dataset=LIST: List of headers to split dataset into. If blank, will use datatype defaults. []
• slimfarmer: Updated from Version 1.9.0.
→ Version 1.10.0: Added appending contents of jobini file to slimsuite=F farm commands.
• slimfinder: Updated from Version 5.3.4.
→ Version 5.3.5: Fixed slimcheck and advanced stats models bug.
→ Version 5.4.0: Modified qregion=X,Y to be 1-L numbering.
• slimparser: Updated from Version 0.5.0.
→ Version 0.5.1: Minor docs and bug fixes.
→ Version 0.6.0: Improved functionality as replacement pureapi with rest=jobid and rest=check functions.
• slimsuite: Updated from Version 1.7.1.
→ Version 1.8.0: Added BUSCOMP and basic test function.
→ Version 1.8.1: Updated documentation and added IUPred2. General tidy up and new example data for protocols paper.
• smrtscape: Updated from Version 2.2.2.
→ Version 2.2.3: Fixed bug where SMRT subreads are not returned by seqlist in correct order. Fixed RQ=0 bug.
• snapper: Updated from Version 1.6.1.
→ Version 1.7.0: Added mapper=minimap setting, compatible with GABLAM v2.30.0 and rje_paf v0.1.0.
© RJ Edwards 2019. Last modified 27 May 2019.
Monday, 2 July 2018
SLiMSuite Downloads
UPDATE: Please see the Downloads page for the most recent release.
The current SLiMSuite release is v1.4.0 (2018-07-02) and can be downloaded by clicking the button (left).
In addition to the tarball available via the links above, SLiMSuite is available as a GitHub repository (right).
See also: Installation and Setup.
Previous Releases
v1.3.0 (2017-12-18)v1.2.0 (2016-09-12)v1.1.0 (2015-11-30)2015-06-01v1.0.0 (2015-01-07)
SLiMSuite release v1.4.0 (2018-06-02) now oline
SLiMSuite release v1.4.0 (2018-07-02) is now on GitHub. The REST servers have also been updated to run this version of the code.
This release of SLiMSuite contains a number of updates related to the REST servers and some new pre-release dev tools in the main repo (but not the *.tgz file).
SeqList has updated sequence summary statistics and grep-based redundancy removal for large genomes.
One major bug fix is a change to parsing Uniprot entries from the website following a change in behaviour of the API.
SLiMSuite updates
Updates in extras/:
• rje_pydocs: Updated from Version 2.16.3.
→ Version 2.16.4: Tweaked formatDocString.
→ Version 2.16.5: Added general commands to docstring HTML for REST servers.
→ Version 2.16.6: Modified parsing to keep DocString for SPyDarm runs.
→ Version 2.16.7: Fixed T/F/FILE option type parsing bug.
Updates in libraries/:
• rje_blast_V2: Updated from Version 2.18.0.
→ Version 2.19.0: Added blastgz=T/F : Whether to zip and unzip BLAST results files [False]
→ Version 2.19.1: Fixed erroneous i=-1 blastprog over-ride but not sure why it was happening.
→ Version 2.20.0: Added localGFF output
→ Version 2.21.0: Added blasttask=X setting for BLAST -task ['megablast']
→ Version 2.22.0: Added dust filter for blastn and setting blastprog based on blasttask
→ Version 2.22.1: Added trimLocal error catching for exonerate issues.
→ Version 2.22.2: Fixed GFF attribute case issue.
• rje_db: Updated from Version 1.8.6.
→ Version 1.9.0: Added comment output to saveToFile().
• rje_disorder: Updated from Version 0.8.
→ Version 1.0.0: Added random disorder function and elevated to v1.x as fully functional for SLiMSuite
→ Version 1.1.0: Added strict option for disorder method selection. Added minorder=X.
→ Version 1.2.0: Added saving and loading scores to IUScoreDir/.
• rje_gff: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Basic functional version.
• rje_hpc: Updated from Version 1.1.
→ Version 1.1.1: Added output of subjob command to log as run.
• rje_html: Updated from Version 0.2.1.
→ Version 0.3.0: Added optional loading of javascript files and stupidtable.js?dev default.
• rje_qsub: Updated from Version 1.9.1.
→ Version 1.9.2: Modified qsub() to return job ID.
• rje_samtools: Updated from Version 1.19.2.
→ Version 1.20.0: Added parsing of BAM file - needs samtools on system. Added minsoftclip=X, maxsoftclip=X and minreadlen=X.
• rje_seq: Updated from Version 3.24.0.
→ Version 3.25.0: 9spec=T/F : Whether to treat 9XXXX species codes as actual species (generally higher taxa) [False]
• rje_seqlist: Updated from Version 1.25.0.
→ Version 1.26.0: Updated sequence statistics and fixed N50 underestimation bug.
→ Version 1.26.1: Fixed median length overestimation bug.
→ Version 1.26.2: Fixed sizesort bug. (Now big to small as advertised.)
→ Version 1.27.0: Added grepNR() method (dev only). Switched default to RevCompNR=T.
→ Version 1.28.0: Fixed second pass NR naming bug and added option to switch off altogether.
→ Version 1.29.0: Added maker=T/F : Whether to extract MAKER2 statistics (AED, eAED, QI) from sequence names [False]
• rje_slimcalc: Updated from Version 0.9.3.
→ Version 0.10.0: Added extra disorder methods to slimcalc.
• rje_taxonomy: Updated from Version 1.2.0.
→ Version 1.3.0: taxtable=T/F : Whether to output results in a table rather than text lists [False]
• rje_tree: Updated from Version 2.15.0.
→ Version 2.16.0: 9spec=T/F : Whether to treat 9XXXX species codes as actual species (generally higher taxa) [False]
→ Version 2.16.1: Modified NSF reading to cope with extra information beyond the ";".
• rje_uniprot: Updated from Version 3.24.1.
→ Version 3.24.2: Updated HTTP to HTTPS. Having some download issues with server failures.
→ Version 3.25.0: Fixed new Uniprot batch query URL. Added onebyone=T/F : Whether to download one entry at a time. Slower but should maintain order [False].
• rje_zen: Updated from Version 1.3.2.
→ Version 1.4.0: Added some more words and "They fight crime!" structure.
Updates in tools/:
• gablam: Updated from Version 2.28.3.
→ Version 2.29.0: Added localGFF=T/F output
• gasp: Updated from Version 1.4.
→ Version 2.0.0: Upgraded to rje_obj framework for REST server.
• gasp_V1: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 1.0: Improved version with second pass.
→ Version 1.1: Improved OO. Restriction to descendant AAs. (Good for BAD etc.)
→ Version 1.2: No Out Object in Objects
→ Version 1.3: Added more interactive load options
→ Version 1.4: Minor tweaks to imports.
• gopher: Updated from Version 3.4.2.
→ Version 3.4.3: Added checking and warning if no bootstraps for orthtree.
• haqesac: Updated from Version 1.11.0.
→ Version 1.12.0: 9spec=T/F : Whether to treat 9XXXX species codes as actual species (generally higher taxa) [False]
• multihaq: Updated from Version 1.3.0.
→ Version 1.4.0: Added SLiMFarmer batch forking if autoskip=F and i=-1.
→ Version 1.4.1: Added haqblastdir=PATH: Directory in which MultiHAQ BLAST2FAS BLAST runs will be performed [./HAQBLAST/]
• pagsat: Updated from Version 2.3.3.
→ Version 2.3.4: Fixed full.fas request bug.
→ Version 2.4.0: Added PAGSAT compile mode to generate comparisons of reference chromosomes across assemblies.
• seqsuite: Updated from Version 1.14.0.
→ Version 1.14.1: Added zentest for testing the REST servers.
→ Version 1.15.0: Added GASP to REST servers.
→ Version 1.16.0: Add rje_gff.GFF to REST servers.
→ Version 1.17.0: Added batch summarise mode.
→ Version 1.18.0: Added rje_apollo.Apollo to REST servers.
→ Version 1.19.0: Tweaked the output of batch summarise, adding Gap% and reducing dp for some fields.
→ Version 1.19.1: Fixed GapPC summarise output to be a percentage, not a fraction.
• slimbench: Updated from Version 2.14.0.
→ Version 2.14.1: Fixed up PPIBench results loading.
→ Version 2.14.2: Fixed ByCloud bug.
→ Version 2.15.0: Updated assessSearchMemSaver() to handle different data types properly. dombench not yet supported.
→ Version 2.16.0: Added ppi hub/slim summary and motif filter for assessment datasets post-rating (still count as OT)
→ Version 2.16.1: Bug-fixing PPI generation from pairwise PPI files.
→ Version 2.16.2: Fixed benchmarking setup bug.
→ Version 2.16.3: Fixed bug when Hub-PPI links fail during PPI Benchmarking.
→ Version 2.17.0: Added output of missing datasets when balanced=T.
→ Version 2.18.0: Added dev OccBench with improved ratings and more efficient results handling. (dev only)
→ Version 2.18.1: Added additional OccBench options (bymotif, occsource, occspec)
→ Version 2.18.2: Fixed problem with source file selection ignoring i=-1.
• slimfarmer: Updated from Version 1.7.0.
→ Version 1.8.0: jobforks=X : Number of forks to pass to farmed out run if >0 [0]
→ Version 1.9.0: daisychain=X : Chain together a set of qsub runs of the same call that depend on the previous job.
• slimfinder: Updated from Version 5.3.3.
→ Version 5.3.4: Fixed terminal (^/$) musthave bug.
• slimsuite: Updated from Version 1.7.0.
→ Version 1.7.1: Added error raising for protected REST alias data.
• smrtscape: Updated from Version 2.2.1.
→ Version 2.2.2: Added dna=T to all SeqList object generation.
• snapper: Updated from Version 1.6.0.
→ Version 1.6.1: Fixed bug for reducing to unique-unique pairings that was over-filtering.
© RJ Edwards 2018. Last modified 2 Jul 2018.
Tuesday, 19 December 2017
SLiMSuite REST Servers updated
The SLiMSuite REST Servers have been updated to the latest release code (v1.3.0). Please report any issues!
SLiMSuite release v1.3.0 (2017-12-18) online
SLiMSuite release v1.3.0 (2017-12-18) is now on GitHub. Funding for SLiMSuite development is proving elusive at present, so this release is a little less organised (and later) than planned. The main additions are various programs in development for PacBio genomics and a draft SLiMSuite parser Shiny app in the new shiny/ directory. The old packages/ directory has also been removed. Check the docs/release/ files and see below for more information on this release.
Another release with improved documentation is currently planned for early 2018. As ever, if you want access to the latest code, email to download the full svn repository.
SLiMSuite updates
Updates in extras/:
• rje_dbase: Updated from Version 2.3.
→ Version 2.3.1: Updated the dbdownload function to recognise individual files and wildcard file lists.
• rje_pydocs: Updated from Version 2.16.3.
→ Version 2.17.4: Tweaked formatDocString.
→ Version 2.17.5: Added general commands to docstring HTML for REST servers.
Updates in legacy/:
Updates in libraries/:
• rje: Updated from Version 4.17.0.
→ Version 4.18.0: Added Roman numeral functions.
→ Version 4.18.1: Updated error handling for full REST output.
→ Version 4.18.2: Fixed rje module call bug.
→ Version 4.19.0: Tweaked Docstring. Added extra parameter catching. Added report of INI loading.
• rje_blast_V2: Updated from Version 2.11.2.
→ Version 2.12.0: Added localidcut %identity filter for GABLAM calculations.
→ Version 2.13.0: Added GFF and SAM output for BLAST local tables for GABLAM, PAGSAT etc.
→ Version 2.14.0: Updated gablamfrag=X and fragmerge=X usage. Fixed localFragFas position output.
→ Version 2.15.0: Fragmerge no longer removes flanks and can be negative for enforced overlap!
→ Version 2.16.0: Added qassemblefas mode for generating fasta file from outfmt 4 run.
→ Version 2.16.1: Improved error messages for BLAST QAssembly.
→ Version 2.17.0: qconsensus=X : Whether to convert QAssemble alignments to consensus sequences (None/Hit/Full) [None]
→ Version 2.17.1: Modified QAssembleFas output sequence names for better combining of hits. Added QFasDir.
→ Version 2.17.2: Modified QAssembleFas output file names for better re-running. Fixed major QConsensus Bug.
→ Version 2.18.0: Added REST output. Fixed QConsensus=Full bug.
• rje_db: Updated from Version 1.8.1.
→ Version 1.8.2: Fixed minor readSet bug.
→ Version 1.8.3: Minor debugging message changes.
→ Version 1.8.4: Cosmetic log message changes.
→ Version 1.8.5: Added saveToFileName() function.
→ Version 1.8.6: Minor IndexReport tweak.
• rje_genbank: Updated from Version 1.5.2.
→ Version 1.5.3: Fixed https genbank download issue.
• rje_menu: Updated from Version 0.4.0.
→ Version 0.5.0: Enabled simpler return tuples.
• rje_obj: Updated from Version 2.2.1.
→ Version 2.2.2: Updated error handling for full REST output.
• rje_qsub: Updated from Version 1.6.3.
→ Version 1.7.0: Added option for email when job started
→ Version 1.8.0: Added modpurge=T/F : Whether to purge loaded modules in qsub job file prior to loading [True]
→ Version 1.9.0: Added precall=LIST : List of additional commands to run between module loading and program call []
→ Version 1.9.1: Removed default module list: causing conflicts. Better to have in INI file.
• rje_samtools: Updated from Version 1.8.1.
→ Version 1.9.0: Added depthplot data generation. (Will need to add R function for plot itself.)
→ Version 1.9.1: Changed mincut default to 0.1.
→ Version 1.10.0: Added readlen output, which is like the depth plot but uses max read length (kb) instead of depth.
→ Version 1.11.0: Added dirnlen=X : Include directional read length data at X bp intervals (depthplot=T; 0=OFF) [500]
→ Version 1.11.1: Minor tweaks to try and speed up pileup parsing.
→ Version 1.12.0: Updated the snpfreq run code to make clearer and check for parsing issues. Set mincut=1 default.
→ Version 1.13.0: Added skiploci=LIST - need to screen out mitochondrion from Illumina Pileup parsing!
→ Version 1.14.0: Added forking of pileup parsing for SNPFreq analysis.
→ Version 1.14.1: Fixed SNPFreq rerunning bug.
→ Version 1.15.0: Added rgraphics=T/F : Whether to generate snpfreq multichromosome plots [True]
→ Version 1.16.0: Add coverage calculation per locus to depth plot table output (depthplot=T).
→ Version 1.16.1: Added reporting of existing files for parsing Pileup.
→ Version 1.17.0: Added parsing of lengths from SAM files to RID file.
→ Version 1.18.0: Updated processing of Treatment and Control without Alt to still limit to SNPTable. Fixed SNPFreq filters.
→ Version 1.19.0: snptableout=T/F : Output filtered alleles to SNP Table [False]
→ Version 1.19.1: Fixed AltLocus SNP table bug.
→ Version 1.19.2: Updated forker parsing to hopefully fix bug.
• rje_seqlist: Updated from Version 1.20.1.
→ Version 1.21.0: Added capacity to add/update database object from self.summarise() even if not seqmode=db. Added filedb mode.
→ Version 1.22.0: Added geneDic() method.
→ Version 1.23.0: Added seqSequence() method.
→ Version 1.24.0: Add NNN gaps option and "delete rest of sequences" to edit().
→ Version 1.24.1: Minor edit bug fix and DNA toggle option.
→ Version 1.25.0: Added loading of FASTQ files in seqmode=file mode.
• rje_sequence: Updated from Version 2.5.3.
→ Version 2.6.0: Added mutation dictionary to Ks calculation.
• rje_slim: Updated from Version 1.12.0.
→ Version 1.12.1: Modified error message.
• rje_slimcalc: Updated from Version 0.9.2.
→ Version 0.9.3: Changed fudge error to warning.
• rje_slimcore: Updated from Version 2.7.7.
→ Version 2.7.8: Fixed batch=FILE error for single input files.
→ Version 2.8.0: Added map and failed output to REST servers and standalone uniprotid=LIST input runs.
→ Version 2.8.1: Updated resfile to be set by basefile if no resfile=X setting given
→ Version 2.9.0: Added separate IUPred long suffix for reusing predictions
• rje_synteny: Updated from Version 0.0.0.
→ Version 0.0.1: Altered problematic ValueError to warnLog()
→ Version 0.0.2: Updated the synteny mappings to be m::n instead of m:n for Excel compatibility.
→ Version 0.0.3: Added catching of the Feature locus/accnum mismatch issue.
• rje_tree: Updated from Version 2.14.0.
→ Version 2.14.1: Fixed clustalw2 makeTree issue.
→ Version 2.15.0: Added IQTree.
• rje_uniprot: Updated from Version 3.22.0.
→ Version 3.23.0: Added accnum map table output. Fixed REST output bug when bad IDs given. Added version and about output.
→ Version 3.24.0: Added pfam out and changed map table headers.
→ Version 3.24.1: Fixed process Uniprot error when uniprot=FILE given.
• rje_zen: Updated from Version 1.3.1.
→ Version 1.3.2: Added some more words.
• snp_mapper: Updated from Version 1.0.0.
→ Version 1.1.0: Added pNS and modified the "Positive" CDS rating to be pNS < 0.05.
→ Version 1.1.1: Updated pNS calculation to include EXT mutations and substitution frequency.
→ Version 1.2.0: SNPByFType=T/F : Whether to output mapped SNPs by feature type (before FTBest filtering) [False]
Updates in tools/:
• gablam: Updated from Version 2.23.0.
→ Version 2.23.1: Added tuplekeys=T to cmd_list as default. (Can still be over-ridden if it breaks things!)
→ Version 2.24.0: Added localidmin and and localidcut as %identity versions of localmin and localcut. (Use for PAGSAT.)
→ Version 2.25.0: Added localsAM=T/F : Save local (and unique) hits data as SAM files in addition to TDT [False]
→ Version 2.26.0: Fixed fragfas output and clarified fullblast=T/F, localmin=X and localcut=X. Set fullblast=T keepblast=T.
→ Version 2.26.1: Fixed keepblast error.
→ Version 2.26.2: Fixed gablamcut fragfas filtering bug.
→ Version 2.26.3: Fixed nrseq=T to use Query OR Hit stat for NR filtering.
→ Version 2.26.4: Minor bug fix to nrchoice command parsing.
→ Version 2.27.0: Fragmerge no longer removes flanks and can be negative for enforced overlap!
→ Version 2.28.0: Added localidmin=PERC to localUnique (and thus Snapper).
→ Version 2.28.1: Fixed missing combinedfas when using existing blastres.
→ Version 2.28.2: Minor bug fix for NRSeq manual choice when i=-1.
→ Version 2.28.3: Fixed NRSeq query sorting bug.
• haqesac: Updated from Version 1.10.2.
→ Version 1.10.3: Added catching of bad query when i=-1.
→ Version 1.11.0: Added resdir=PATH [./HAQESAC/] for d>0 outputs.
• multihaq: Updated from Version 1.2.2.
→ Version 1.3.0: MultiCut : Restrict BLAST to the top X hits from each database [100]
• pagsat: Updated from Version 1.11.2.
→ Version 1.11.3: Added reference=FILE as alias for refgenome=FILE. Fixed orphan delete bug.
→ Version 1.12.0: Tidying up and documenting outputs. Changed default minloclen=250 and minlocid=95. (LTR identification.)
→ Version 2.0.0: Major overhaul of outputs to improve consistency and clarity. Added Snapper to main run.
→ Version 2.1.0: Added localSAM output.
→ Version 2.1.1: Fixed the case of some output files.
→ Version 2.1.2: Fixed some issues with reverse hits in Snapper and application of minlocid.
→ Version 2.2.0: Added mapout=T, which is recommended for first run if going to subsequently tidy. (Run tidy on mapfile.)
→ Version 2.2.1: Tried to fix covplot bug in compare=FILES mode.
→ Version 2.2.2: Cleaned up *.map.* output for SAMPhaser output files. Added tidy/mapfas option selection.
→ Version 2.2.3: Added #NOTE to tidy and fixed makesnp=T bug.
→ Version 2.2.4: Fixed `fragrevcomp=F` bug for Gene and Protein TopHits.
→ Version 2.2.5: Hopefully really fixed makesnp=T bug now!
→ Version 2.2.6: Fixed Haploid tidy sequence output naming bug.
→ Version 2.2.7: Fixed Compare File path bug & dropped some empty outputs.
→ Version 2.3.0: Minor bug fixes and extra tidy options (join gaps and multi-deletes).
→ Version 2.3.1: Minor bug fixes.
→ Version 2.3.2: Updated the synteny mappings to be m::n instead of m:n for Excel compatibility.
→ Version 2.3.3: Fixed bad assembly sequence name bug.
• pagsat_V1: Created/Renamed/moved.
→ Version 1.0.0: Initial working version for based on rje_pacbio assessment=T.
→ Version 1.1.0: Fixed bug with gene and protein summary data. Removed gene/protein reciprocal searches. Added compare mode.
→ Version 1.1.1: Added PAGSAT output directory for tidiness!
→ Version 1.1.2: Renamed the PacBio class PAGSAT.
→ Version 1.2.0: Tidied up output directories. Added QV filter and Top Gene/Protein hits output.
→ Version 1.2.1: Added casefilter=T/F : Whether to filter leading/trailing lower case (low QV) sequences [True]
→ Version 1.3.0: Added tophitbuffer=X and initial synteny analysis for keeping best reference hits.
→ Version 1.4.0: Added chrom-v-contig alignment files along with *.ordered.fas.
→ Version 1.4.1: Made default chromalign=T.
→ Version 1.4.2: Fixed casefilter=F.
→ Version 1.5.0: diploid=T/F : Whether to treat assembly as a diploid [False]
→ Version 1.6.0: mincontiglen=X : Minimum contig length to retain in assembly [1000]
→ Version 1.6.1: Added diploid=T/F to R PNG call.
→ Version 1.7.0: Added tidy=T/F option. (Development)
→ Version 1.7.1: Updated tidy=T/F to include initial assembly.
→ Version 1.7.2: Fixed some bugs introduced by changing gablam fragment output.
→ Version 1.7.3: Added circularise sequence generation.
→ Version 1.8.0: Added orphan processing and non-chr naming of Reference.
&r
Monday, 12 September 2016
SLiMSuite release v1.2.0 (2016-09-12) online
The long-overdue September 2016 release of SLiMSuite 2016-09-12 - v1.2.0 is now on GitHub. Apart from a few bug fixes, the main updates in this release are to the tools for PacBio genomics, notably PAGSAT, SMRTSCAPE and a new SNP Mapping tool, Snapper. These are still in development and need further documentation but are ready for use with a little help. Please get in touch if you are interested. Proper documentation and example use will hopefully follow soon, as the first PacBio yeast paper is written.
GABLAM has had some minor tweaks for improved function with Snapper, PAGSAT and another developmental tool that will be in the next release (REVERT - available via the REST servers). These have been focused on the fragfas=T output of fragmented BLAST hits based on local alignments. This includes addition of a new default to reverse complement reverse hits (fragrevcomp=T) and the separation of parameters for splitting up local hits into multiple fragments (gablamfrag=X) and merging close/overlapping fragments (fragmerge=X).
SLiMSuite updates in this release
Updates in extras/:
• rje_pydocs: Updated from Version 2.16.2.
→ Version 2.16.3: Fixed docstring REST parsing to work with _V* modules.
Updates in libraries/:
• rje: Updated from Version 4.15.1.
→ Version 4.16.0: Added list2dict(inlist,inkeys) and dict2list(indict,inkeys) functions.
→ Version 4.16.1: Improved handling of integer parameters when given bad commands.
→ Version 4.17.0: Added extra functions to randomList()
• rje_blast_V2: Updated from Version 2.9.1.
→ Version 2.10.0: Added nocoverage calculation based on local alignment table.
→ Version 2.11.0: Added localFragFas output method.
→ Version 2.11.1: Fixed snp local table revcomp bug. [Check this!]
→ Version 2.11.2: Fixed GABLAM calculation bug when '*' in protein sequences.
• rje_db: Updated from Version 1.8.0.
→ Version 1.8.1: Added sfdict to saveTable output.
• rje_genbank: Updated from Version 1.3.2.
→ Version 1.4.0: Added addtags=T/F : Add locus_tag identifiers if missing - needed for gene/cds/prot fasta output [False]
→ Version 1.4.1: Fixed genetic code warning.
→ Version 1.5.0: Added setupRefGenome() method based on PAGSAT code.
→ Version 1.5.1: Fixed logskip append locus sequence file bug.
→ Version 1.5.2: Fixed addtag(s) bug.
• rje_hprd: Updated from Version 1.2.
→ Version 1.2.1: Fixed "PROTEIN_ARCHITECTURE" bug.
• rje_menu: Updated from Version 0.3.
→ Version 0.4.0: Changed handling of default for exiting menu loop. May affect behaviour of some existing menus.
• rje_mitab: Updated from Version 0.2.0.
→ Version 0.2.1: Fixed redundant evidence/itype bug (primarily dip)
• rje_obj: Updated from Version 2.1.3.
→ Version 2.2.0: Added screenwrap=X.
→ Version 2.2.1: Improved handling of integer parameters when given bad commands.
• rje_samtools: Updated from Version 0.1.0.
→ Version 0.2.0: Added majmut=T/F : Whether to restrict output and stats to positions with non-reference Major Allele [False]
→ Version 1.0.0: Major reworking. Old version frozen as rje_samtools_V0.
→ Version 1.1.0: Added snptabmap=X,Y alternative SNPTable mapping and read_depth statistics []. Added majref=T/F.
→ Version 1.2.0: Added developmental combining of read mapping onto two different genomes.
→ Version 1.3.0: Major debugging and code clean up.
→ Version 1.4.0: Added parsing of read number (to link SNPs) and fixed deletion error at same time. Added rid=T/F and snponly=T/F.
→ Version 1.5.0: Added biallelic=T/F : Whether to restrict SNPs to pure biallelic SNPs (two alleles meeting mincut) [False]
→ Version 1.5.1: Fixed REF/Ref ALT/Alt bug.
→ Version 1.6.0: Added majfocus=T/F : Whether the focus is on Major Alleles (True) or Mutant/Reference Alleles (False) [True]
→ Version 1.7.0: Added parsing of *.sam files for generating RID table.
→ Version 1.8.0: Added read coverage summary/checks.
→ Version 1.8.1: Fixed issue when RID file not generated by pileup parsing. Set RID=True by default to avoid issues.
• rje_samtools_V0: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 0.1.0: Modified version to handle multiple loci per file. (Original was for single bacterial chromosomes.)
→ Version 0.2.0: Added majmut=T/F : Whether to restrict output and stats to positions with non-reference Major Allele [False]
• rje_seq: Updated from Version 3.23.0.
→ Version 3.24.0: Added REST seqout output.
• rje_seqlist: Updated from Version 1.15.3.
→ Version 1.15.4: Fixed REST server output bug.
→ Version 1.15.5: Fixed reformat=fasta default issue introduced from fixing REST output bug.
→ Version 1.16.0: Added edit=T sequence edit mode upon loading (will switch seqmode=list).
→ Version 1.17.0: Added additional summarise=T output for seqmode=db.
→ Version 1.18.0: Added revcomp to reformat options.
→ Version 1.19.0: Added option log description for deleting sequence during edit.
→ Version 1.20.0: Added option to give a file of changes for edit mode.
→ Version 1.20.1: Fixed edit=FILE deletion bug.
• rje_sequence: Updated from Version 2.5.2.
→ Version 2.5.3: Fixed genetic code warning error.
• rje_slimcore: Updated from Version 2.7.5.
→ Version 2.7.6: Added feature masking log info or warning.
→ Version 2.7.7: Switched feature masking OFF by default to give consistent Uniprot versus FASTA behaviour.
• rje_synteny: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
• rje_taxonomy: Updated from Version 1.1.0.
→ Version 1.2.0: Added storage of Parents.
• rje_tree: Updated from Version 2.13.0.
→ Version 2.14.0: Added cladeSpec().
• rje_uniprot: Updated from Version 3.21.4.
→ Version 3.22.0: Tweaked REST table output.
• rje_xref: Updated from Version 1.8.0.
→ Version 1.8.1: Added rest run mode to avoid XRef table output if no gene ID list is given. Added `genes` and `genelist` as `idlist=LIST` synonym.
→ Version 1.8.2: Catching self.dict['Mapping'] error for REST server.
• snp_mapper: Updated from Version 0.4.0.
→ Version 0.5.0: Added CDS rating.
→ Version 0.6.0: Added AltFT mapping mode (map features to AltLocus and AltPos)
→ Version 0.7.0: Added additional fields for processing Snapper output. (Hopefully will still work for SAMTools etc.)
→ Version 0.8.0: Added parsing of GFF file from Prokka.
→ Version 0.8.1: Corrected "intron" classification for first position of features. Updated FTBest defaults.
→ Version 1.0.0: Version that works with Snapper V1.0.0. Not really designed for standalone running any more.
Updates in tools/:
• comparimotif_V3: Updated from Version 3.12.
→ Version 3.13.0: Added REST server function.
• gablam: Updated from Version 2.20.0.
→ Version 2.21.0: Added nocoverage Table output of regions missing from pairwise SNP Table.
→ Version 2.21.1: Added fragrevcomp=T/F : Whether to reverse-complement DNA fragments that are on reverse strand to query [True]
→ Version 2.22.0: Added description to HitSum table.
→ Version 2.22.1: Added localaln=T/F to keep local alignment sequences in the BLAST local Table.
→ Version 2.22.2: Fixed local output error. (Query/Qry issue - need to fix this and make consistent!)
→ Version 2.22.3: Fixed blastv and blastb error: limit also applies to individual pairwise hits!
→ Version 2.23.0: Divided GablamFrag and FragMerge.
• pagsat: Updated from Version 1.6.1.
→ Version 1.7.0: Added tidy=T/F option. (Development)
→ Version 1.7.1: Updated tidy=T/F to include initial assembly.
→ Version 1.7.2: Fixed some bugs introduced by changing gablam fragment output.
→ Version 1.7.3: Added circularise sequence generation.
→ Version 1.8.0: Added orphan processing and non-chr naming of Reference.
→ Version 1.9.0: Modified the join sorting and merging. Added better tracking of positions when trimming.
→ Version 1.9.1: Added joinmargin=X : Number of extra bases allowed to still be considered an end local BLAST hit [10]
→ Version 1.10.0: Added weighted tree output and removed report warning.
→ Version 1.10.1: Fixed issue related to having Description in GABLAM HitSum tables.
→ Version 1.10.2: Tweaked haploid core output.
→ Version 1.10.3: Fixed tidy bug for RevComp contigs and switched joinsort default to Identity. (Needs testing.)
→ Version 1.10.4: Added genetar option to tidy out genesummary and protsummary output. Incorporated rje_synteny.
→ Version 1.10.5: Set gablamfrag=1 for gene/protein hits.
→ Version 1.11.0: Consolidated automated tidy mode and cleaned up some excess code.
→ Version 1.11.1: Added option for running self-PAGSAT of ctidX contigs versus haploid set. Replaced ctid "X" with "N".
→ Version 1.11.2: Fixed Snapper run choice bug.
• pingu_V4: Updated from Version 4.5.3.
→ Version 4.6.0: Added hubonly=T/F : Whether to restrict pairwise PPI to those with both hub and spoke in hublist [False]
→ Version 4.6.1: Fixed some ppifas=T/F bugs and added combineppi=T/F : Whether to combine all spokes into a single fasta file [False]
→ Version 4.6.2: Added check/filter for multiple SpokeUni pointing to same sequence. (Compilation redundancy mapping failure!)
→ Version 4.6.3: Fixed issue with 1:many SpokeUni:Spoke mappings messing up XHub.
→ Version 4.7.0: Added ppidbreport=T/F : Summary output for PPI compilation of evidence/PPIType/DB overlaps [True]
→ Version 4.8.0: Fixed report duplication issue and added additional summary output
• qslimfinder: Updated from Version 2.1.0.
→ Version 2.1.1: Switched feature masking OFF by default to give consistent Uniprot versus FASTA behaviour.
• seqsuite: Updated from Version 1.11.0.
→ Version 1.11.1: Redirected PacBio to call SMRTSCAPE.
→ Version 1.11.2: Fixed batchrun batchlog=False log error.
→ Version 1.12.0: Added Snapper.
• slimfarmer: Updated from Version 1.4.3.
→ Version 1.4.4: Modified default vmem request to 126GB from 127GB.
→ Version 1.4.5: Updated BLAST loading default to 2.2.31
• slimfinder: Updated from Version 5.2.1.
→ Version 5.2.2: Added warnings for ambocc and minocc that exceed the absolute minima. Updated docstring.
→ Version 5.2.3: Switched feature masking OFF by default to give consistent Uniprot versus FASTA behaviour. Fixed FTMask=T/F bug.
• slimparser: Updated from Version 0.3.3.
→ Version 0.3.4: Tweaked error messages.
→ Version 0.4.0: Added simple json format output.
• slimprob: Updated from Version 2.2.4.
→ Version 2.2.5: Fixed FTMask=T/F bug.
• slimsearch: Updated from Version 1.7.
→ Version 1.7.1: Minor modification to docstring. Preparation for update to SLiMSearch 2.0 optimised for proteome searches.
• slimsuite: Updated from Version 1.5.1.
→ Version 1.5.2: Updated XRef REST call.
→ Version 1.6.0: Removed SLiMCore as default. Default will now show help.
• smrtscape: Updated from Version 1.8.0.
→ Version 1.9.0: Updated empirical preassembly mapefficiency calculation.
→ Version 1.10.0: Added batch processing of subread files.
→ Version 1.10.1: Fixed bug in batch processing.
• snapper: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 0.1.0: Tidied up with improved run pickup.
→ Version 0.2.0: Added FASTQ and improved CNV output along with all features.
→ Version 0.2.1: Fixed local output error. (Query/Qry issue - need to fix this and make consistent!) Fixed snp local table revcomp bug.
→ Version 0.2.2: Corrected excess CNV table output (accnum AND shortname).
→ Version 0.2.3: Corrected "intron" classification for first position of features. Updated FTBest defaults.
→ Version 1.0.0: Working version with completed draft manual. Added to SeqSuite.
→ Version 1.0.1: Fixed issues when features missing.
Thursday, 10 December 2015
BioInfoSummer2015 SLiMSuite Workshop
Dr Richard Edwards, University of New South Wales
Thursday 10th December 2015
Session outline
Click for slides.
Part I: Theory
- Introduction to workshop
- What are SLiMs?
- What is SLiMSuite
Part II: Practice
- Installing/running SLiMSuite
- Data types and main input formats
- Motif discovery using the SLiMSuite REST Servers
- Motif discovery using the SLiMScape app for Cytoscape
Additional help and documentation
General information about SLiMs and motif discovery can be found in the literature. Some good places to start are the recent ELM 2016 paper and our 2015 Methods in Molecular Biology review as well as the SLiMScape app paper:
- Motif discovery review paper (PDF)
- SLiMScape app paper (PDF)
- SLiMFinder manual (PDF)
- SLiMProb manual (PDF)
- CompariMotif manual (PDF)
For information about SLiMSuite, please visit the EdwardsLab webpage and the SLiMSuite blog. Help and documentation for the REST servers can also be found at the REST homepage. If in doubt, please email: richard.edwards@unsw.edu.au.
Several EdwardsLab publications also cover motifs and SLiMSuite tools.
Installing/Running SLiMSuite
NOTE: For this workshop, you do not need to install SLiMSuite. You will need Cytoscape and the SLiMScape app for the later parts.
The current SLiMSuite release is 2015-11-30 and can be downloaded by clicking the button (left).
In addition to the tarball available via the links above, SLiMSuite is now available as a GitHub repository (right).
See also: Installation and Setup.
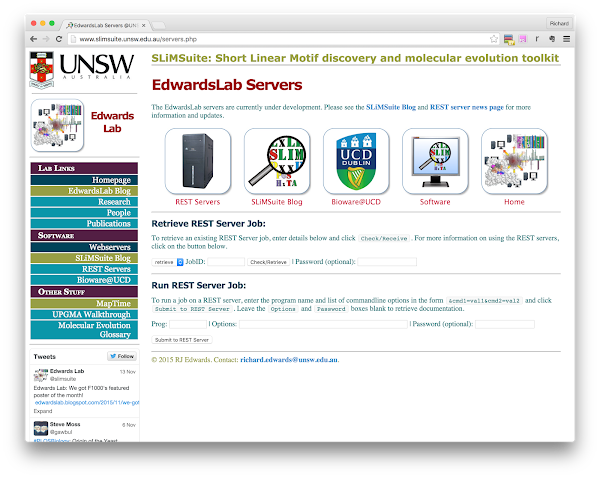
For this workshop, we will primarily be running the tools (and looking at pre-generated results) via the online servers:
Data types and main input formats
From a computer science perspective, input and output for SLiMSuite is just plain ASCII text. This makes it easy to plug SLiMSuite into existing scripts and pipelines - and manually view/edit any input or output files if required. However, “plain text” is not very informative, and SLiMSuite actually deals with a lot of different formats of plain text (from a “human formatting” rather than “file type” point of view). The documentation is currently in the process of being updated to better reflect these formats but some commandline options will still simply list FILE, FILES or FILELIST as input parameters: see the accompanying descriptions to see what format these should be. Ask if it’s not clear! (File format documentation will also be added to the SLiMSuite blog, so check there.)
Within SLiMSuite, each file type has a distinct “file extension” that denotes the file type. Note that these are not enforced for input, although some programs may not always recognise the right format if a different extension is used. If you get odd input behaviour/errors that you do not understand, see if changing the file extensions helps. If you want a common file extension to be auto-recognised, let me know and I might be able to add it. SLiMSuite file extensions will not necessarily be recognised by other programs. NOTE: Operating systems will sometimes hide file extensions by default. If you are getting very confused, or have problems of extra *.txt extensions on everything, try changing the system settings. (And/or becoming familiar with command-line file manipulation.)
The main input formats for SLiM discovery are:
- A source of protein sequence data. This could be a protein FASTA file, a Uniprot plain text file, or a list of Uniprot accession numbers to download. For some tools, a single Uniprot accession number will work.
- A source of motif (regular expression) definitions. This is only required if looking for known (or other pre-defined) motifs and/or wanting to compare a set of de novo predictions with known motifs. A number of different formats are accepted for motif input, including SLiMFinder (summary) results and ELM downloads. The simplest/easiest is a plain text file of regular expressions. For more on motif regular expression formats, please see Edwards and Palopoli 2015.
Common motif discovery tasks
Jobs can be run and retrieved at: http://www.slimsuite.unsw.edu.au/servers.php. (This is a bit easier than making the URL directly, although this is also an option as we will see.)
NOTE: Some of the jobs take a while to run and the SLiMSuite servers have limited resources. It would therefore be useful if you could click on the example JobID links rather than trying to run every example REST command yourself. The first output tab (and the log tab) will show you the run times for that job, so you can see which jobs are fast or slow before you experiment.
Task 1: Find known SLiMs in a protein (ELM/SLiMProb)
ELM. Visit http://http://www.elm.eu.org/ and enter your protein of choice as Uniprot identifier or accession number in the box. (Identifiers will auto-complete and fill in some extra details.) For non-Uniprot protein sequences, you can also enter fasta format.
Try this now with P03070 (LT_SV40) or P03254 (E1A_ADE02). Each of them should have a True Positive LIG_Rb_LxCxE_1 motif.
SLiMProb. We can do a similar search using the SLiMProb REST server (paste the contents of the grey box onto the end of the http://rest.slimsuite.unsw.edu.au/ URL):
slimprob&uniprotid=E1A_ADE02&motifs=elm
JobID: 15120800029
NOTE: The ELM alias currently searches the 2015 ELM classes.
Task 2: Find custom SLiMS in a protein (SLiMProb)
slimprob&uniprotid=E1A_ADE02&motifs=LxCxE,PxDLS
JobID: 15120800031
Task 3: Finding proteome-wide occurrence of a motif using Bioware (SLiMSearch)
The SLiMSearch server is accessible at: http://slim.ucd.ie/slimsearch/. This has been recently updated to Version 4 and now brings in a lot of information, so it is recommended that you read the Help pages for the server.
Example (LIG_CtBP_PxDLS_1): http://slim.ucd.ie/rest/#/slimsearch/annotations?jobId=7R8Tvssm9HEdjWW7jQsgEHUfP0VlHdR6
Human protein PRDM16 is particularly interesting: it does not have an annotated ELM but does match a region annotated to interact with CTBP1. (See the Region column - Expand the instance Feature annotations for a clearer look.) This kind of search can be a good way of identifying new instances of known motifs - some of which may be in the literature but may not have yet made it into database annotation.
The ELM definition for this motif P[LVIPME][DENS][LM][VASTRG] is very degenerate with a lot of hits - over-prediction is a big problem in motif discovery. We can try to make the definition a little tighter as the expense of some instances, using another tool called SLiMMaker:
slimmaker&peptides=LIG_CtBP_PxDLS_1&iterate=T&align=F&minfreq=0.67&minseq=2
JobID: 15120600004
Repeating the SLiMSearch analysis with the redefined motif (P[EILMV][DN]L[ARST]) gives a greater density of known ELMs (see the Motif column) in the top ranked motifs: http://slim.ucd.ie/rest/#/slimsearch/annotations?jobId=L41BRpXQ1oTD6ByDuUSqjWbQZ22WBKbw.
Task 4: Predicting novel SLiMs de novo in a set of proteins (SLiMFinder)
SLiMFinder is designed to look for convergently evolved motifs that are shared between unrelated proteins. For example, we can look at the proteins known (in ELM) to contain the LIG_PCNA_PIPBox_1. As SLiMs are generally in disordered regions, we will switch disorder masking on with dismask=T, which uses IUPred to predict globular regions, which are masked out:
slimfinder&uniprotid=LIG_PCNA_PIPBox_1&dismask=T
JobID: 15120800001
(We will look at the UPC and motif cloud output among others.)
Task 5: Identifying known motifs from de novo predictions (CompariMotif)
When you have a lot of motif predictions, it can be tiresome and error-prone to manually scan them for things that look familiar. SLiMSuite has a tool called CompariMotif, which compares sets of motifs for similarity.
The comparimotif server can take motif files/lists (like SLiMProb or SLiMFinder output directly. These are given to the &motifs and/or &searchdb options: if no &searchdb is given then the input motifs are searched against themselves. (This can be useful if clouding goes a bit wrong.)
To pass the output of one server to another, use the format: &cmd=jobid:XXXXXX:OUTFMT, where XXXXXX is the Job ID and OUTFMT is the desired output format. E.g.:
comparimotif&motifs=jobid:15120800001:main&searchdb=LIG_PCNA_PIPBox_1
JobID: 15120900004
The server is currently in development so output is not sorted usefully yet. This is more of a problem if searching against many SLiMs:
comparimotif&motifs=jobid:15120800001:main&searchdb=elm
JobID: 15120900005
The best advice is to save the compare output table (retrieve&jobid=15120900005&outfmt=compare), open it up in Excel and sort on Score. Alternatively, use the CompariMotif server at http://bioware.ucd.ie.
Task 6: SLiM prediction with conservation masking (SLiMFinder)
Masking is important as it reduces the search space. It can also reduce the signal if it incorrectly masks some true positives but for larger datasets the reduction in "noise" can be more important. As well as dismask=T/F there are several other masking options in SLiMSuite:
- low complexity masking (
ONby default) - N-terminal methionines (
ONby default) - conservation-based masking (
OFFby default) - Uniprot feature masking (
OFFby default) - Motif masking (
OFFby default)
For custom sequence input, there is also the option for custom masking based on upper/lower case. For now, we will just look at conservation masking, as this has been shown to improve sensitivity in PPI data. For example, a 2013 compilation of CTBP1 interactors does not yield a significant motif:
slimfinder&uniprotid=CTBP1&dismask=T&runid=CtBP1-DisMask
JobID: 15120900002
But if consmask=T is also switched on:
slimfinder&uniprotid=CTBP1&dismask=T&consmask=T&runid=CtBP1-ConsMask
JobID: 15120900003
The importance of correcting for evolutionary relationships
The UPC correction can be switched off with efilter=F. Many motif prediction tools calculate estimated expectations without such correction. This can result is massive biases due to shared evolutionary history, which swamp any convergent SLiM evolution signal, for example with the LIG_CtBP_PxDLS_1 ELM proteins:
slimfinder&uniprotid=LIG_CtBP_PxDLS_1&dismask=T&runid=CtBP-NoEFilter&efilter=F
JobID: 15120800036
Task 7: Look for enrichment or depletion of motifs in a set of proteins (SLiMProb)
We can investigate why the PxDLS motif did not come back with just disorder masking by looking at its enrichment using SLiMProb. When given multiple proteins, SLiMProb will use the same UPC correction as SLiMFinder but also return statistics without UPC correction and simply treating all the sequences as one giant sequence. It can, for example, be used to investigate different definitions of a motif:
slimprob&uniprotid=CTBP1&dismask=T&runid=CtBP1-DisMask&motifs=PxDLS,P[LVIPME][DENS][LM][VASTRG],Px[DE][LM][ST]
JobID: 15120900016
In this case, we can see that even though the "true" motif has the most support, it is also expected to occur more by chance. It is enriched, but not enough to survive the multiple testing correction of SLiMChance.
Though not of interest here, the pUnd statistics can be used to look for depletion/avoidance of a particular motif in a dataset.
Task 8: Find novel motifs from a conservation pattern (SLiMPrints)
Patterns of evolutionary conservation can also be used to directly identify regions of proteins that look like motifs. The tool we have developed for this is called SLiMPrints, which can be run at the Bioware SLiMPrints server. For example, we can look for motif-like regions in one of the CtBP PPI partners, FOG1_HUMAN (Q8IX07): http://bioware.ucd.ie/~compass/biowareweb/cgi-bin/PHP_helper_files/slimprintsInfo.php?jobId=e7GZLf
This protein has a bunch of significant motif-like regions, including the PxDLS motif region at rank 7: http://bioware.ucd.ie/~proviz/ProViz/alignmentViewer/drawer.php?uniprotid=Q8IX07&slim=GPIDL&slimpos=793&column=794.5&width=80&collapse=false
(Note how the precise motif is rarely returned by de novo predictors.)
Task 9: Using the SLiMScape app to visualise a server job
We're now going to fire up Cytoscape and have a quick look at the SLiMScape app. This is fairly well described in the paper, so we will just look at the main ways to run the server. If you've not used Cytoscape before, you'll want to visit the Cytoscape website and watch the introduction video, before installing it.
The simplest is to retrieve an existing run:
- In the SLiMFinder tab, enter
15120900003in the Run ID box and hit Retrieve. - Apply the default layout.
- Explore the results. Connections are UPC relationships in the data.
Task 10: Running QSLiMFinder through SLiMScape
Now let's imagine we had seen the SLiMPrints results from above for FOG1_HUMAN and knew that it interacted with CtBP1. We could ask the specific question if any motifs in FOG1_HUMAN were enriched in the rest of the PPI dataset. We do this by using QSLiMFinder and giving Q8IX07 as the query. (&query=Q8IX07 on the server.)
First, add a node to the network and change its name to Q8IX07. Enter this in the Query Sequence box then highlight all of the nodes before hitting Run QSLiMFinder:
JobID: 15120900007
This is the essence of molecular mimicry and we could use the same approach to see if E1A_ADE02 shares any motifs by adding P03254 and using it as a query:
JobID: 15120900008
Task 11: Building PPI networks for analysis
The most useful thing of having access to SLiMSuite through Cytoscape is to be able to use it to explore PPI networks and select nodes for analysis. There are in-built tools to get PPI data into Cytoscape. For SLiMSuite, the ID must be a Uniprot ID or accession number, or a Node must have "Uniprot" attribute.
The SLiMSuite REST server also provides some methods for getting PPI data into Cytoscape (and/or for use on the server), using the PINGU server. This is still under development and so the documentation of the available PPI data is currently limited, but just get in touch if you want to use it. (Currently human only.)
PPI data is retrieved by entering one or more gene symbols as a &hublist, optionally along with a &ppisource (see the ppisource alias):
pingu&hublist=CTBP1,CTBP2&ppisource=intact
JobID: 15120900009
This can be used directly for &uniprotid input using the &rest=uniprot output:
slimfinder&uniprotid=jobid:15120900009:uniprot&dismask=T&consmask=T&runid=CtBP1and2
JobID: 15120900011
Alternatively, the PPI data can be imported into Cytoscape using the pairwise table:
- Start a new session. (Later you can workout how to import and merge networks.)
- Import network from URL: http://rest.slimsuite.unsw.edu.au/retrieve&jobid=15120900009&rest=pairwise
- Rename the
HubUniandSpokeUnifields tonameand attribute them toSource NodeandTarget Nodeattributes. MakeHubtheSource,SpoketheTargetandEvidencetheInteraction Typethen import. - Select the nodes that are shared interactors of both CtBP proteins.
- Modify the masking settings to include disorder, conservation and feature masking.
- Hit Run:
JobID: 15120900013
Monday, 30 November 2015
SLiMSuite release v1.1.0 (2015-11-30) online
The November 2015 release of SLiMSuite v1.1.0 (2015-11-30) in now on GitHub. This is intermediate release in preparation for the BioInfoSummer 2015 SLiMSuite workshop and contains a few minor modifications to SLiMSuite programs. The main updates are preliminary versions of some tools for PacBio genomics, notably PAGSAT and SMRTSCAPE. These are still in development and need further documentation and testing before use is advised.
The SeqSuite Genbank parser has some bug fixes for reverse complemented protein sequences with introns, and initial capacity for different codon tables. (This has been implemented for yeast, so only NCBI transl_tables 1-3 currently implemented: please get in touch if you want to use this program with other codon tables.)
SLiMSuite updates in this release
Updates in libraries/:
• rje: Updated from Version 4.14.0.
→ Version 4.14.1: Fixed matchExp method to be able to handline multilines. (Shame re.DOTALL doesn’t work!)
→ Version 4.14.2: Modified integer commands to read/convert floats.
→ Version 4.15.0: Added intList() and numList() functions.
• rje_db: Updated from Version 1.7.5.
→ Version 1.7.6: Added table.opt[‘Formatted’] = Whether table data has been successfully formatted using self.dataFormat()
→ Version 1.7.7: Added option to constrain table splitting to certain field values.
→ Version 1.8.0: Added option to store keys as tuples for correct sorting. (Make default at some point.)
• rje_genbank: Updated from Version 1.3.1.
→ Version 1.3.2: Fixed bug in reverse complement sequences with introns.
• rje_iridis: Updated from Version 1.10.
→ Version 1.10.1: Attempted to fix SLiMFarmer batch run problem. (Should not be setting irun=batch!)
→ Version 1.10.2: Trying to clean up unknown 30s pause. Might be freemem issue?
• rje_obj: Updated from Version 2.1.2.
→ Version 2.1.3: Modified integer commands to read/convert floats.
• rje_qsub: Updated from Version 1.6.2.
→ Version 1.6.3: Tweaked the showstart command for katana.
• rje_samtools: Created/Renamed/moved.
→ Version 0.0: Initial Compilation.
→ Version 0.1.0: Modified version to handle multiple loci per file. (Original was for single bacterial chromosomes.)
• rje_seqlist: Updated from Version 1.11.0.
→ Version 1.12.0: Added peptides/qregion reformatting and region=X,Y.
→ Version 1.13.0: Added summarise=T option for generating some summary statistics for sequence data. Added minlen & maxlen.
→ Version 1.14.0: Added splitseq=X split output sequence file according to X (gene/species) [None]
→ Version 1.15.0: Added names() method.
→ Version 1.15.1: Fixed bug with storage and return of summary stats.
→ Version 1.15.2: Fixed dna2prot reformatting.
→ Version 1.15.3: Fixed summarise bug (n=1).
• rje_sequence: Updated from Version 2.4.1.
→ Version 2.5.0: Added yeast genome renaming.
→ Version 2.5.1: Modified reverse complement code.
→ Version 2.5.2: Tried to speed up dna2prot code.
• rje_slimcalc: Updated from Version 0.9.
→ Version 0.9.1: Modified combining of motif stats to handle expectString format for individual values.
→ Version 0.9.2: Changed default conscore in docstring to RLC.
• rje_slimcore: Updated from Version 2.7.3.
→ Version 2.7.4: Fixed walltime server bug.
→ Version 2.7.5: Fixed feature masking.
• rje_slimlist: Updated from Version 1.7.2.
→ Version 1.7.3: Fixed bug that could not accept variable length motifs from commandline. Improved error message.
• rje_taxonomy: Updated from Version 1.0.
→ Version 1.1.0: Added parsing of yeast strains.
• rje_tree: Updated from Version 2.11.2.
→ Version 2.12.0: Added treeLen() method.
→ Version 2.13.0: Updated PNG saving with R to use newer code.
• rje_uniprot: Updated from Version 3.21.3.
→ Version 3.21.4: Fixed Feature masking. Should this be switched off by default?
• rje_xref: Updated from Version 1.6.0.
→ Version 1.7.0: Added comments=LIST ist of comment line prefixes marking lines to ignore (throughout file) [‘//’,’%’]
→ Version 1.7.1: Added xreformat=T/F : Whether to apply field reformatting to input xrefdata (True) or just xrefs to map (False) [False]
→ Version 1.8.0: Added recognition and parsing of yeast.txt XRef file from Uniprot (http://www.uniprot.org/docs/yeast.txt)
• snp_mapper: Created/Renamed/moved.
→ Version 0.0: Initial Compilation. Batch mode for mapping SNPs needs updating.
→ Version 0.1: SNP mapping against a GenBank file.
→ Version 0.2: Fixed complement strand bug.
→ Version 0.3.0: Updated to work with RATT(/Mummer?) snp output file. Improved docs.
→ Version 0.4.0: Major reworking for easier updates and added functionality. (Convert to 1.0.0 when complete.)
Updates in tools/:
• gablam: Updated from Version 2.19.2.
→ Version 2.20.0: Added SNP Table output.
• gopher: Updated from Version 3.4.1.
→ Version 3.4.2: Removed GOPHER System Exit on IOError to prevent breaking of REST server.
• pagsat: Created/Renamed/moved.
→ Version 1.0.0: Initial working version for based on rje_pacbio assessment=T.
→ Version 1.1.0: Fixed bug with gene and protein summary data. Removed gene/protein reciprocal searches. Added compare mode.
→ Version 1.1.1: Added PAGSAT output directory for tidiness!
→ Version 1.1.2: Renamed the PacBio class PAGSAT.
→ Version 1.2.0: Tidied up output directories. Added QV filter and Top Gene/Protein hits output.
→ Version 1.2.1: Added casefilter=T/F : Whether to filter leading/trailing lower case (low QV) sequences [True]
→ Version 1.3.0: Added tophitbuffer=X and initial synteny analysis for keeping best reference hits.
→ Version 1.4.0: Added chrom-v-contig alignment files along with *.ordered.fas.
→ Version 1.4.1: Made default chromalign=T.
→ Version 1.4.2: Fixed casefilter=F.
→ Version 1.5.0: diploid=T/F : Whether to treat assembly as a diploid [False]
→ Version 1.6.0: mincontiglen=X : Minimum contig length to retain in assembly [1000]
→ Version 1.6.1: Added diploid=T/F to R PNG call.
• peptcluster: Updated from Version 1.5.1.
→ Version 1.5.2: Improved clarity of warning message.
• pingu_V4: Updated from Version 4.5.0.
→ Version 4.5.1: Debugging missing identifiers and indexing speed. Added good and bad DB.
→ Version 4.5.2: Fixed SIF output and changed names to sif-* for opening in browser.
→ Version 4.5.3: Updated REST output.
• seqsuite: Updated from Version 1.8.0.
→ Version 1.9.0: Added PAGSAT and SMRTSCAPE.
→ Version 1.9.1: Fixed HAQESAC setobjects=True error.
→ Version 1.10.0: Added batchrun=FILELIST batcharg=X batch running mode.
→ Version 1.11.0: Added SAMTools and Snapper/SNP_Mapper.
• slimbench: Updated from Version 2.10.0.
→ Version 2.10.1: Updated ELM Source URLs.
• slimfarmer: Updated from Version 1.4.2.
→ Version 1.4.3: Added recognition of missing slimsuite programs and switching to slimsuite=F.
• slimfinder: Updated from Version 5.2.0.
→ Version 5.2.1: Fixed ambocc<1 and minocc<1 issue. (Using integers rather than floats.) Fixed OccRes Sig output format.
• slimparser: Updated from Version 0.3.1.
→ Version 0.3.2: Fixed issue reading files for full output.
→ Version 0.3.3: Tidied output names when restbase=jobid.
• slimprob: Updated from Version 2.2.3.
→ Version 2.2.4: Improved slimcalc output (s.f.).
• slimsuite: Updated from Version 1.5.0.
→ Version 1.5.1: Changed disorder to iuscore to avoid module conflict.
• smrtscape: Created/Renamed/moved.
→ Version 0.0.0: Initial Compilation.
→ Version 1.0.0: Initial working version for server.
→ Version 1.1.0: Added xnlist=LIST : Additional columns giving % sites with coverage >= Xn [10,25,50,100].
→ Version 1.2.0: Added assessment -> now PAGSAT.
→ Version 1.3.0: Added seed and anchor read coverage generator (calculate=T).
→ Version 1.3.1: Deleted assessment function. (Now handled by PAGSAT.)
→ Version 1.4.0: Added new coverage=T function that incorporates seed and anchor subreads.
→ Version 1.5.0: Added parseparam=FILES with paramlist=LIST to parse restricted sets of parameters.
→ Version 1.6.0: New SMRTSCAPE program building on PacBio v1.5.0. Added predict=T/F option.
→ Version 1.6.1: Updated parameters=T to incorporate that the seed read counts as X=1.
→ Version 1.7.0: Added *.summary.tdt output from subread summary analysis. Added minreadlen.
→ Version 1.8.0: preassembly=FILE: Preassembly fasta file to assess/correct over-fragmentation (use seqin=FILE for subreads)
Thursday, 1 October 2015
SLiMSuite data types and file formats
SLiMSuite is designed to be a suite of programs that enable you to navigate your way through most of the main motif discovery tasks. Well, I say designed but it would probably be more accurate to say evolved. All the programs within SLiMSuite arose from research needs within the lab. As a result, they are heavily biased to the kind of data that we analyse and data sources that we use. However, it should be fairly easy to get data from other formats and sources into SLiMSuite.
From a computer science perspective, input and output for SLiMSuite is just plain ASCII text. This makes it easy to plug SLiMSuite into existing scripts and pipelines - and manually view/edit any input or output files if required. However, “plain text” is not very informative, and SLiMSuite actually deals with a lot of different formats of plain text (from a “human formatting” rather than “file type” point of view). The documentation is currently in the process of being updated to better reflect these formats but some commandline options will still simply list FILE, FILES or FILELIST as input parameters: see the accompanying descriptions to see what format these should be. Ask if it’s not clear! (File format documentation will also be added to the SLiMSuite blog, so check there.)
Within SLiMSuite, each file type has a distinct “file extension” that denotes the file type. Note that these are not enforced for input, although some programs may not always recognise the right format if a different extension is used. If you get odd input behaviour/errors that you do not understand, see if changing the file extensions helps. If you want a common file extension to be auto-recognised, let me know and I might be able to add it. SLiMSuite file extensions will not necessarily be recognised by other programs. NOTE: Operating systems will sometimes hide file extensions by default. If you are getting very confused, or have problems of extra *.txt extensions on everything, try changing the system settings. (And/or becoming familiar with command-line file manipulation.)
The main file types used by SLiMSuite are:
MOTIFS= A list of SLiM motif patterns. SLiMSuite has its own motif format but a number of other formats will also work when given as input. This includes a plain list of regex patterns, and results tables from other SLiMSuite programs. [*.motifs]ACCLIST= A list of Uniprot accession numbers. [*.acc]SEQFILE= A file containing biological sequences - usually protein sequences. (Some of the non-SLiM programs will use nucleotides sequences.) These can either be in fasta format (seeFASFILE) or Uniprot plain text format (see DATFILE). [*.fas,*.dat]FASFILE= A fasta file of (unaligned) protein sequences. [*.fas]DATFILE= Uniprot plain text format [*.dat]ALNFILE= Aligned fasta file [*.aln.fas]DSVFILE= Delimiter separated value text file. The delimiter will be auto-recognised if possible as a tab [*.tdt,*.tsv], comma [*.csv] or whitespace [*.txt], or can be set withdelimit=Xif not recognised. Note:delimit=Xinput may not work with every program, so it is safest to use a consistent files name. Thedelimit=Xparameter is more commonly used to control output format.TDTFILE= Tab delimited text file [*.tdt,*.tsv]CSVFILE= Comma separated text file [*.csv]PPIFILE= Delimited text file withHubandSpoke(gene symbol) fields and preferably alsoHubUni(uniprot),SpokeUni(uniprot) andEvidencefields.GENELIST= Plain text list of gene symbols.XREFDATA= Delimited text file that links gene symbols to identifiers from other databases.
See also:
SLiM discovery
The main input formats for SLiM discovery are:
- A source of protein sequence data. This could be a protein FASTA file, a Uniprot plain text file, or a list of Uniprot accession numbers to download. For some tools, a single Uniprot accession number will work.
- A source of motif (regular expression) definitions. This is only required if looking for known (or other pre-defined) motifs and/or wanting to compare a set of de novo predictions with known motifs. A number of different formats are accepted for motif input, including SLiMFinder (summary) results and ELM downloads. The simplest/easiest is a plain text file of regular expressions. For more on motif regular expression formats, please see Edwards and Palopoli 2015.
The main output formats are delimited text files.
Subscribe to:
Posts (Atom)